Architecture
High-level guide to llm-d architecture. Start here, then dive into specific guides.
Core Components
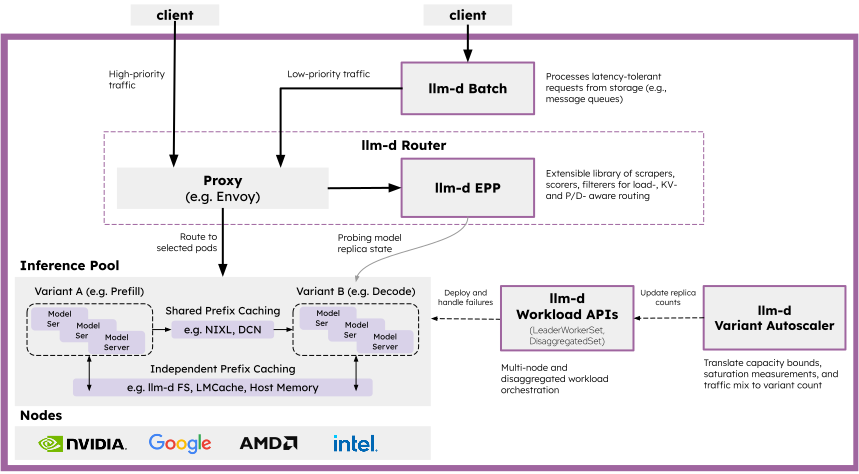
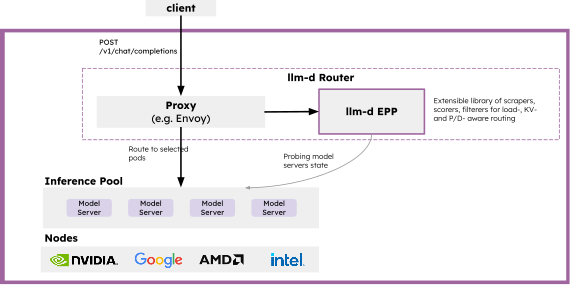
The llm-d architecture is built around three primary concepts: the Router, the InferencePool, and the Model Server.
-
llm-d Router - The intelligent entry point for inference requests. It provides LLM-aware load balancing, request queuing, and policy enforcement. It is composed of two functional parts:
- Proxy: A high-performance L7 proxy conformant with the Gateway API Inference Extension (GAIE) that accepts user requests and consults the EPP via the
ext-procprotocol to determine the optimal destination. - Endpoint Picker (EPP): The routing engine that scores and selects model server pods based on real-time metrics, KV-cache affinity, and configured policies.
- Proxy: A high-performance L7 proxy conformant with the Gateway API Inference Extension (GAIE) that accepts user requests and consults the EPP via the
-
InferencePool - The API that groups Model Server pods serving the same base model via a label selector. Conceptualized as an "LLM-optimized Service", it serves as the discovery target for the Router. Additionally:
- Variant - A logical sub-grouping of Model Server pods within an InferencePool, expressed through pod labels rather than a dedicated resource. Variants distinguish model servers based on shared characteristics such as serving role (e.g., prefill or decode), cost profile, performance profile (throughput, latency), or other operational attributes.
-
Model Server - The inference engine (such as vLLM or SGLang) that executes the model on hardware accelerators (GPUs, TPUs, HPUs).
Advanced Patterns
llm-d's core design can be extended with optional advanced patterns:
KV Cache Management
llm-d provides a comprehensive ecosystem for managing and reusing the KV cache across the inference pool. This includes:
- Prefix-Cache Aware Routing: Heuristic and precise techniques to maximize cache hits.
- KV-Cache Indexing: Event-driven tracking of cache state across all model servers.
- KV Offloading: Tiered storage hierarchy (CPU, SSD) for extending cache capacity.
- P2P Prefix Cache Sharing: Pulling cached prefix KV blocks from a peer's CPU tier instead of recomputing them.
See KV Cache Management for an overview of how these components compose.
Disaggregated Serving
In disaggregated serving, a single inference request is split into multiple phases (e.g., Prefill and Decode) handled by specialized workers. The llm-d Router orchestrates this flow by selecting both a prefill and a decode endpoint and coordinating the KV-cache transfer between them.
See Disaggregation for complete details.
Predicted Latency-Based Routing
The llm-d Router can be extended with "consultant" sidecars that provide advanced signals for routing decisions. The primary implementation is the Latency Predictor, which enables routing based on predicted ITL and TTFT.
- Latency Predictor: Trains an XGBoost model online to predict request latency for better endpoint scoring and SLO enforcement.
Batch Inference
Batch and offline inference workloads are handled by two modules that can be deployed independently or together. The Batch Gateway provides an OpenAI-compatible Batch API for job management, while the Async Processor dispatches queued requests with flow-control gating. When composed, the Batch Gateway delegates dispatch to the Async Processor.
See Batch Inference for details on the batch inference design.
Autoscaling
llm-d supports proactive, SLO-aware autoscaling driven by metrics exported by the EPP. KEDA's Prometheus scaler reads those signals — queue depth, pool saturation, token backlog, or estimated latency against an SLO — and creates and owns the HPA that scales model server replicas. No custom controller or Prometheus Adapter is required.
The Workload Variant Autoscaler (WVA), which globally optimized replica placement across variants and inference pools, is deprecated.
See Autoscaling for complete details.