NVIDIA-Nemotron-3-Ultra-550B on H200
This recipe is optimized for agentic code generation; see the agentic workloads section of the Models overview for the workload framing, and the GLM-5.2 and Qwen3-Coder-480B guides for the other models benchmarked against the same workload.
Overview
This guide deploys RedHatAI/NVIDIA-Nemotron-3-Ultra-550B-A55B-FP8-block on 8 H200 nodes, prefill/decode disaggregated into 6 prefill and 2 decode replicas to absorb the large ISL:OSL ratio of multi-turn agentic sessions (heavy prefill, lighter decode). The configuration layers the agentic optimizations onto disaggregated serving:
- P/D disaggregation so heavy prefill never stalls decode, stabilizing ITL.
- Disagg-aware, token-aware prefix-cache routing: the prefill profile keeps prefix groups on cache-warm endpoints with the prefix-cache affinity filter and picks by queued prefill token load; the decode profile picks the endpoint with the fewest active requests.
- KV cache offloading to CPU DRAM —
200 GiBper model server (~1.6 TBacross the 8 replicas) — to extend the cacheable working set far beyond HBM for long, resumable sessions. - FP8 block weights + FP8 KV cache to fit the
~563 GBof weights atTP=8and leave KV headroom; the MoE is served with Expert Parallelism. VLLM_PREFIX_CACHE_RETENTION_INTERVAL=0to raise multi-turn prefix-cache hit rates. This is enabled here becauseRedHatAI/NVIDIA-Nemotron-3-Ultra-550B-A55B-FP8-blockis a Mamba-hybrid model (NemotronHForCausalLM); vLLM rejects the flag on full-attention models, so it is set per-deployment rather than in the baseline manifests.
🚧 This deployment uses development images (the endpoint-picker and the disaggregation routing sidecar) for the P/D-disaggregation scheduling plugins. Pin them to a release before relying on this in production.
Default Configuration
| Parameter | Value |
|---|---|
| Model | RedHatAI/NVIDIA-Nemotron-3-Ultra-550B-A55B-FP8-block |
| Accelerator | NVIDIA H200 (8 nodes, 8 GPUs each) |
| Serving topology | P/D disaggregated — 6 prefill replicas, 2 decode replicas |
| TP size / EP size | TP=8, EP enabled |
| KV cache | FP8-quantized, with ~1.6 TB CPU offload (200 GiB/replica) |
Supported Accelerators and Model Servers
This guide includes configurations for the following accelerator and model server combinations:
| Accelerator | ACCELERATOR_TYPE | Served model | vLLM | Notes |
|---|---|---|---|---|
| NVIDIA H200 | gpu | RedHatAI/NVIDIA-Nemotron-3-Ultra-550B-A55B-FP8-block | 🟡 community | 8 nodes × 8 H200 · P/D disaggregated, 6 prefill + 2 decode replicas × TP=8 · INFRA_PROVIDER: base (HuggingFace download), gke (model from a GCS bucket) |
✅ validated: covered by a nightly E2E workflow · 🟡 community: maintained by the hardware vendor or community, not covered by nightly E2E · ❌ not supported: tracked in the linked issue · — no configuration.
Prerequisites
-
Have the proper client tools installed on your local system to use this guide.
-
Create a HuggingFace token and export it as
HF_TOKENin your shell. -
(Optional) Install the monitoring stack if you plan to enable Prometheus monitoring.
-
(
INFRA_PROVIDER=gkeonly) Copy the model to a Google Cloud Storage bucket the cluster can mount, as described in Downloading the Model to Your GCS Bucket.
Get the guide
Every command below runs from a local clone of the llm-d repository: the manifests, Helm values, and Kustomize overlays it applies live next to this guide. Set the branch and clone the repo (if you already have a checkout, skip this and run the remaining commands from inside it):
export BRANCH=main
git clone https://github.com/llm-d/llm-d.git && cd llm-d && git checkout ${BRANCH}
Configure the environment
Set the guide-specific environment variables:
export REPO_ROOT=$(realpath $(git rev-parse --show-toplevel))
export GUIDE_NAME=nemotron-3-ultra
export NAMESPACE=llm-d-nemotron-3-ultra
export MONITORING=false # options: false, true
export MONITORING_VALUES=
export ACCELERATOR_TYPE=gpu # options: gpu
export MODEL_SERVER=vllm # options: vllm
export INFRA_PROVIDER=base # options: base, gke
export MODEL=RedHatAI/NVIDIA-Nemotron-3-Ultra-550B-A55B-FP8-block # the model both overlays serve
source ${REPO_ROOT}/guides/env.sh # defines GAIE_VERSION, ROUTER_CHART_VERSION, router chart URLs, and CURL_TEST_IMAGE
Install the Gateway API Inference Extension CRDs:
# GAIE_URL is automatically calculated from GAIE_VERSION at ${REPO_ROOT}/guides/env.sh
kubectl apply -f https://github.com/kubernetes-sigs/gateway-api-inference-extension/${GAIE_URL}/v1-manifests.yaml
Install the LeaderWorkerSet controller with the DisaggregatedSet API (skip if your cluster already runs LWS v0.11.1 or newer with enableDisaggregatedSet=true):
# helm upgrade never updates CRDs, so apply the chart's CRDs first (see LWS
# "Upgrade by Helm"); this upgrades them on clusters that run an older LWS.
helm pull oci://registry.k8s.io/lws/charts/lws --version=${LWS_VERSION} --untar
kubectl apply --server-side --force-conflicts -f lws/crds
helm upgrade --install lws oci://registry.k8s.io/lws/charts/lws \
  --version=${LWS_VERSION} \
  --namespace lws-system --create-namespace \
  --set enableDisaggregatedSet=true \
  --wait --timeout 300s
Create a target namespace for the installation:
kubectl create namespace ${NAMESPACE} --dry-run=client -o yaml | kubectl apply -f -
Create the llm-d-hf-token secret in your target namespace with the key HF_TOKEN matching a valid HuggingFace token to pull models:
kubectl create secret generic llm-d-hf-token \
  --from-literal="HF_TOKEN=${HF_TOKEN}" \
  --namespace "${NAMESPACE}" \
  --dry-run=client -o yaml | kubectl apply -f -
Installation Instructions
1. Deploy the llm-d Router
Prepare the paths to the helm values files for the llm-d router. This deployment uses the
disaggregation-aware router values
(router/nemotron-3-ultra.values.yaml), which run
separate prefill and decode scheduling profiles:
# Paths to values files
export ROUTER_BASE_VALUES="${REPO_ROOT}/guides/recipes/router/base.values.yaml"
export ROUTER_VALUES="${REPO_ROOT}/guides/models/${GUIDE_NAME}/router/${GUIDE_NAME}.values.yaml"
(Optional) Enable Prometheus monitoring on the llm-d router by defining the helm values file (requires installing the monitoring stack mentioned in Prerequisites):
# only when MONITORING=true:
export MONITORING_VALUES="-f ${REPO_ROOT}/guides/recipes/router/features/monitoring.values.yaml"
Deploy the router in Standalone Mode, with an Envoy sidecar in front of the router. Keep the release name ${GUIDE_NAME}: the verification steps look up the ${GUIDE_NAME}-epp Service by that name. To front the router with a Kubernetes Gateway instead, see Gateway Mode in the Optimized Baseline.
helm install ${GUIDE_NAME} \
  ${ROUTER_STANDALONE_CHART} \
  -f ${ROUTER_BASE_VALUES} \
  ${MONITORING_VALUES} \
  -f ${ROUTER_VALUES} \
  -n ${NAMESPACE} --version ${ROUTER_CHART_VERSION}
2. Deploy the Model Server
This guide provides two ways to deploy the model server. The default one (INFRA_PROVIDER = base) is to download the RedHatAI/NVIDIA-Nemotron-3-Ultra-550B-A55B-FP8-block model from HuggingFace every time.
However, the model is ~560GB in size. Downloading a model of this scale directly from HuggingFace can take over an hour, and because every deployment triggers a new download, it creates a significant bottleneck.
To save time and accelerate the deployment process, we highly recommend saving the model to a Google Cloud Storage (GCS) bucket and accessing it directly from there. Please check the Readme for this suggested deployment.
Apply the Kustomize overlay for the Nemotron-3-Ultra H200 deployment:
kubectl apply -n ${NAMESPACE} \
  -k ${REPO_ROOT}/guides/models/${GUIDE_NAME}/modelserver/${ACCELERATOR_TYPE}/${MODEL_SERVER}/${INFRA_PROVIDER}/
This deploys one DisaggregatedSet (pd-disagg-vllm) with 6 prefill and 2 decode replicas. Wait for it to become
available (model load is large; the startup probe allows about two hours):
kubectl wait --for=condition=Available disaggregatedset/pd-disagg-vllm -n ${NAMESPACE} --timeout=7200s
(Optional) Deploy the monitoring resources for model servers (requires installing the monitoring stack mentioned in Prerequisites):
# only when MONITORING=true:
kubectl apply -n ${NAMESPACE} -k ${REPO_ROOT}/guides/recipes/modelserver/components/monitoring-pd
Verification
1. Get the IP of the Proxy
export IP=$(kubectl get service ${GUIDE_NAME}-epp -n ${NAMESPACE} -o jsonpath='{.spec.clusterIP}')
2. Send Test Requests
Send a completion request from a temporary pod inside the cluster:
kubectl run curl-test --rm -i --restart=Never \
  --image=${CURL_TEST_IMAGE} \
  --namespace="${NAMESPACE}" \
  --env="IP=${IP}" \
  --env="MODEL=${MODEL}" \
  -- /bin/sh -c 'curl -sS -X POST "http://${IP}/v1/completions" -H "Content-Type: application/json" -d "{\"model\": \"${MODEL}\", \"prompt\": \"Explain how a simple agent loop works in 3 sentences.\"}"'
Check that the router reaches a model server that serves MODEL: the response must name the model and carry generated tokens:
# The router must reach a model server that serves MODEL and returns tokens
kubectl run serve-check --rm -i --restart=Never \
  --image=${CURL_TEST_IMAGE} \
  --namespace="${NAMESPACE}" \
  --env="IP=${IP}" \
  --env="MODEL=${MODEL}" \
  -- /bin/sh -c 'R=$(curl -sS -X POST "http://${IP}/v1/completions" -H "Content-Type: application/json" -d "{\"model\": \"${MODEL}\", \"prompt\": \"Say hello.\", \"max_tokens\": 16}")
    echo "${R}" | grep -q "\"model\":\"${MODEL}\"" && echo "${R}" | grep -q "\"choices\"" \
      && echo "OK: ${MODEL} served through the router" \
      || { echo "FAIL: ${R}"; exit 1; }'
Driving It with a Coding Agent
This deployment ships ready-to-use client configs for two coding agents, both pre-pointed at the
served model. First, port-forward the router's OpenAI-compatible endpoint to localhost:8000
(the EPP service exposes it on port 80):
kubectl port-forward -n ${NAMESPACE} service/${GUIDE_NAME}-epp 8000:80
Claude Code — source the environment file
(claude.env) and launch:
source ${REPO_ROOT}/guides/models/${GUIDE_NAME}/modelserver/gpu/vllm/claude.env && claude
opencode — point OPENCODE_CONFIG at the provided config
(opencode.json) and launch:
OPENCODE_CONFIG="${REPO_ROOT}/guides/models/${GUIDE_NAME}/modelserver/gpu/vllm/opencode.json" opencode
Benchmarking
This guide comes with an inference-perf benchmark preset (defined in inference-perf.yaml) designed for agentic code-generation workloads with multi-turn interactions and tool usage. The configuration parameters include:
| Workload Characteristic | Metric / Distribution Type | Min | Max | Mean / Constant | Std Dev | Description |
|---|---|---|---|---|---|---|
| Shared System Prompt | Constant | - | - | 3,000 tokens | - | Common base instructions, libraries, and API schemas shared across all agent instances. Highly cacheable. |
| Dynamic System Prompt | Lognormal | 10,000 | 990,000 | 160,000 tokens | 233,600 | Repository context, file indexes, and user-specific code context. Large and variable context. |
| Turns per Conversation | Lognormal | 1 | 3,000 | 540 turns | 48,600 | The depth of the agentic reasoning/conversational loop. Multi-turn interactions require sustaining long-lived sessions. |
| Input Tokens per Turn | Lognormal | 100 | 10,000 | 1,500 tokens | 1,200 | Ongoing prompt extensions (e.g., test logs, user follow-ups, modified code blocks) during conversation. |
| Output Tokens per Turn | Lognormal | 50 | 10,000 | 425 tokens | 825 | Model generations per turn, which are generally smaller than inputs but can spike when generating large files. |
| Tool Call Latency | Lognormal | 1 sec | 100 sec | 15 sec | 55 sec | Simulated delay for external tool execution (e.g., running tests, linting, or shell commands) between turns. |
1. Run the Benchmark
inference-perf.yaml runs an
inference-perf job that replays the workload
above against the ${GUIDE_NAME}-epp Service. Set the per-run parameters, render it, and apply it:
# Benchmark parameters. CONCURRENCY_LEVEL is the number of concurrent coding sessions
# to drive; NUM_REQUESTS is fixed at 20 per session; SEED is varied per concurrency level
# so prompts don't overlap across runs (matches the published results below).
export CONCURRENCY_LEVEL=40
export NUM_REQUESTS=$((20 * CONCURRENCY_LEVEL))
export SEED=$((7 + CONCURRENCY_LEVEL))

kubectl delete job inference-perf -n ${NAMESPACE} --ignore-not-found
envsubst < ${REPO_ROOT}/guides/models/${GUIDE_NAME}/inference-perf.yaml | kubectl apply -n ${NAMESPACE} -f -
2. Collect the Results
Follow the job's logs until it completes:
kubectl logs -n ${NAMESPACE} job/inference-perf -f
Benchmark Results
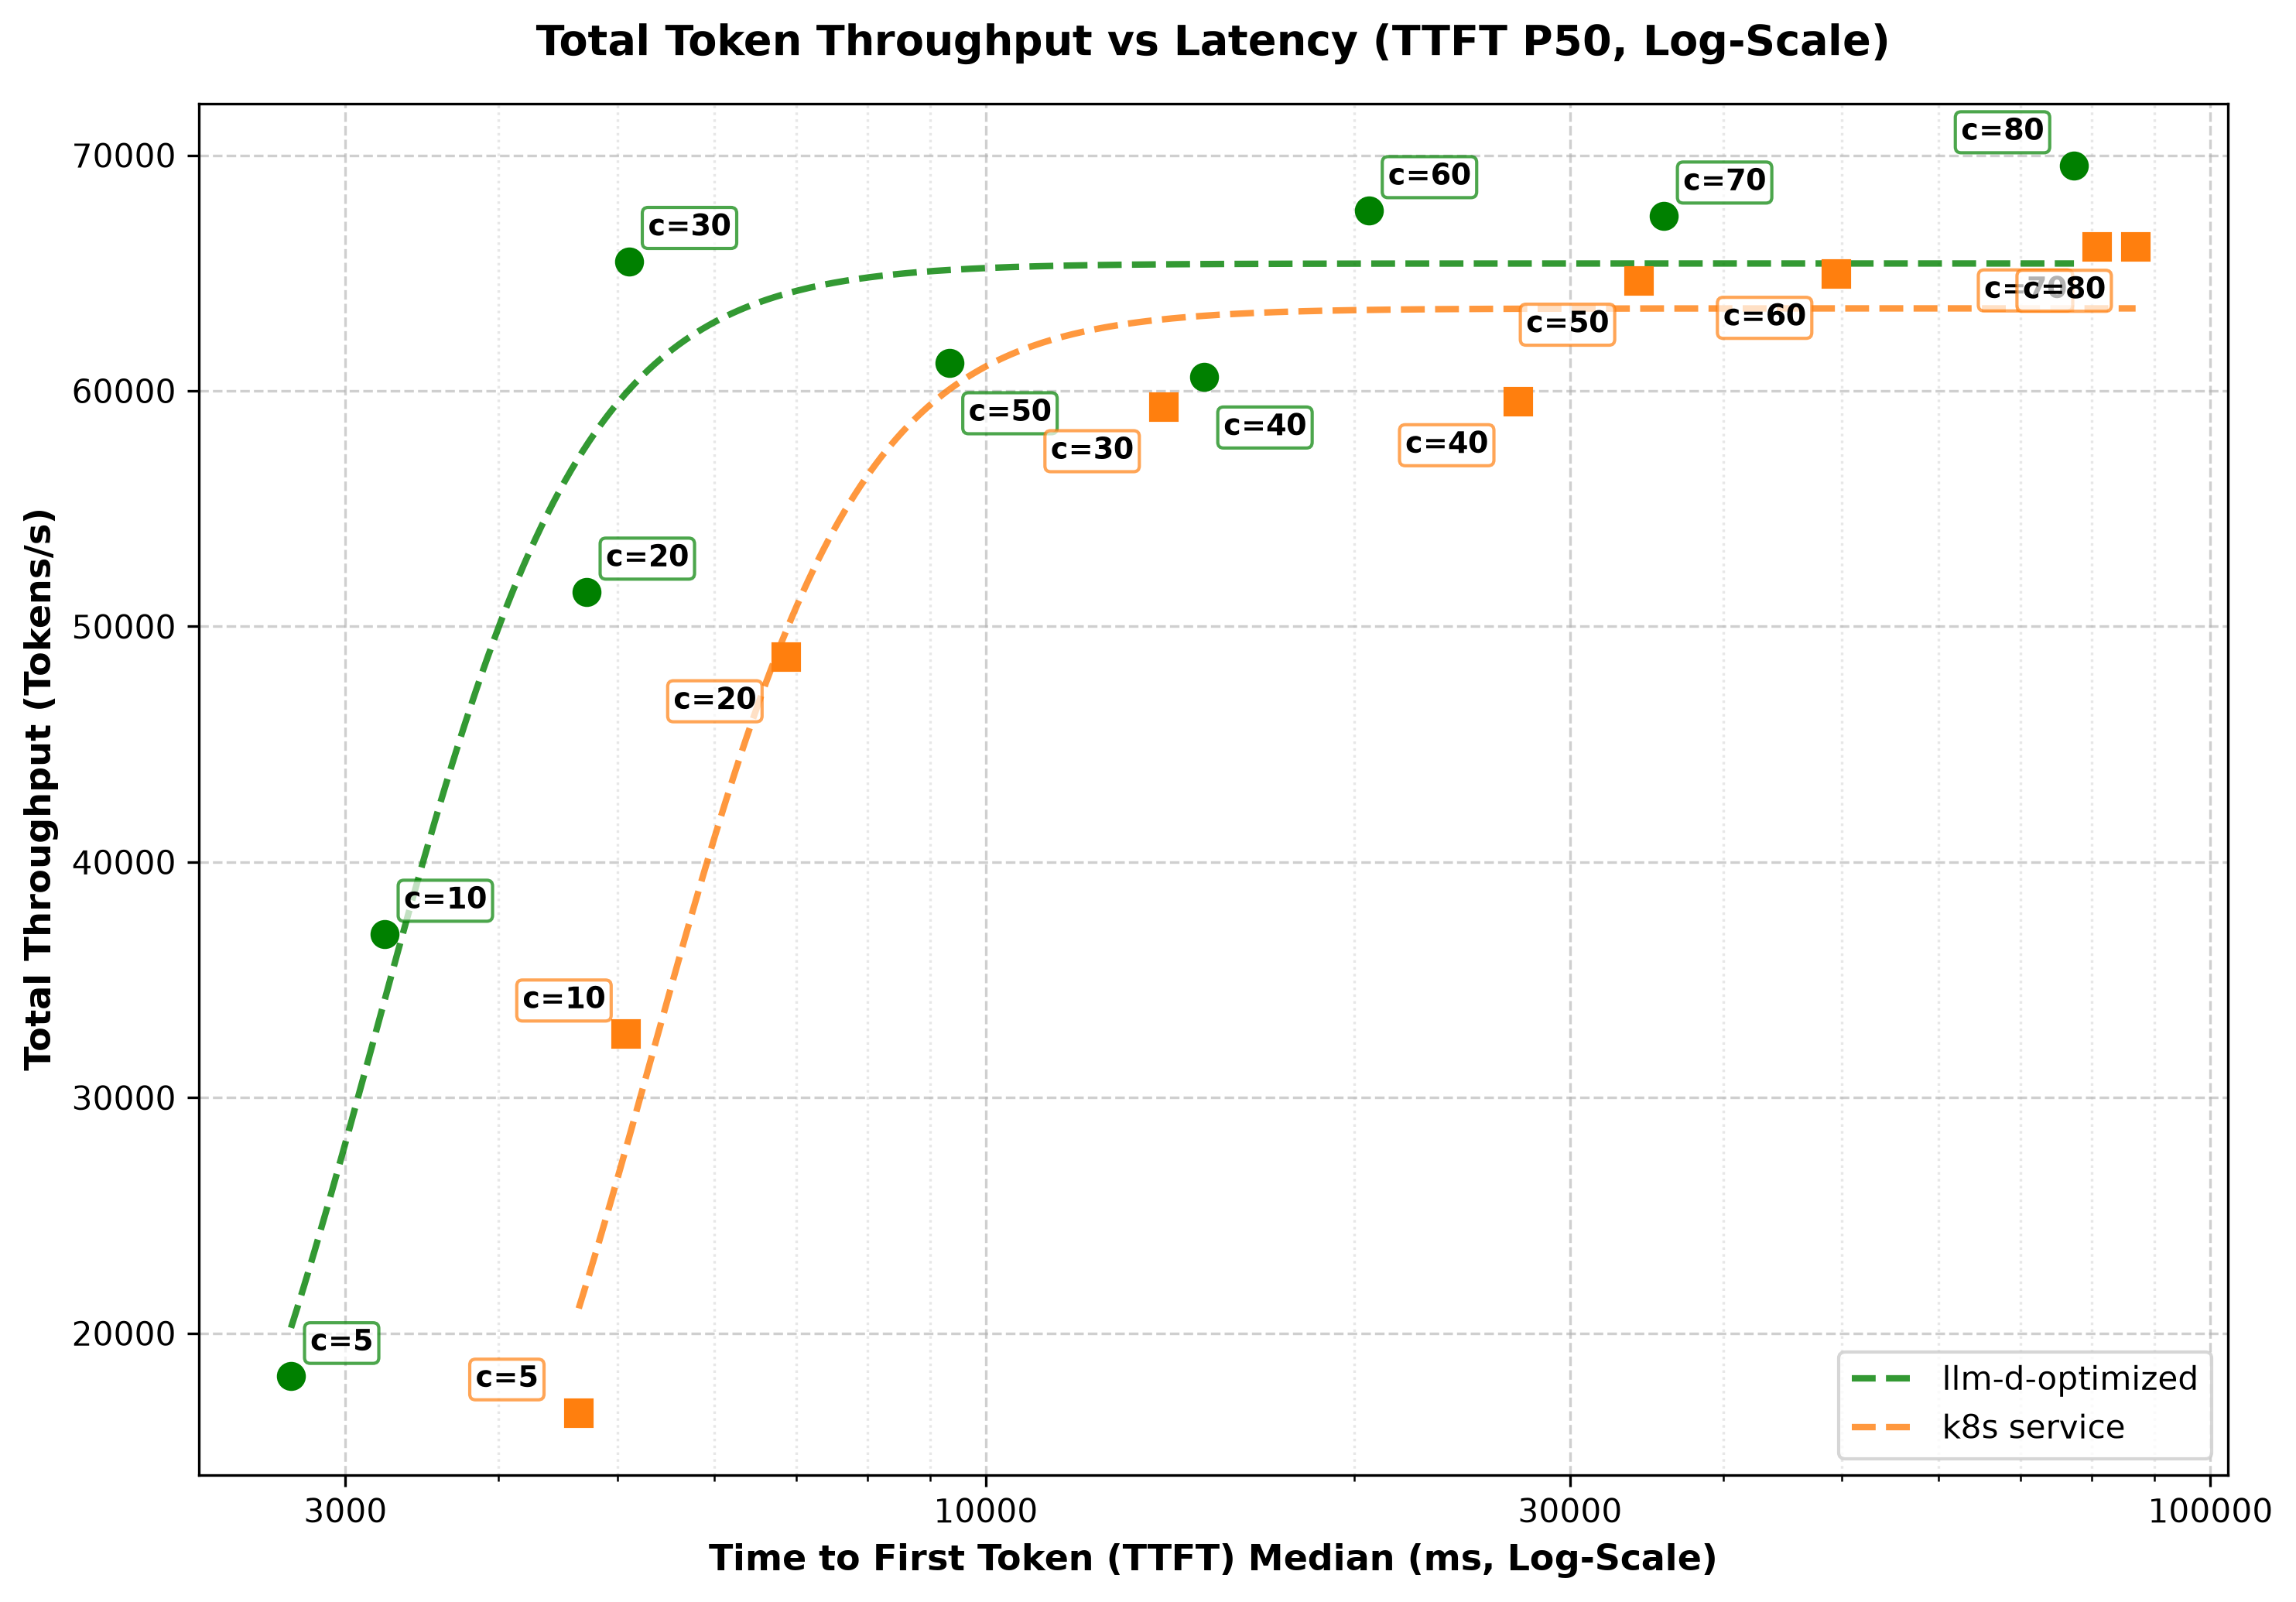
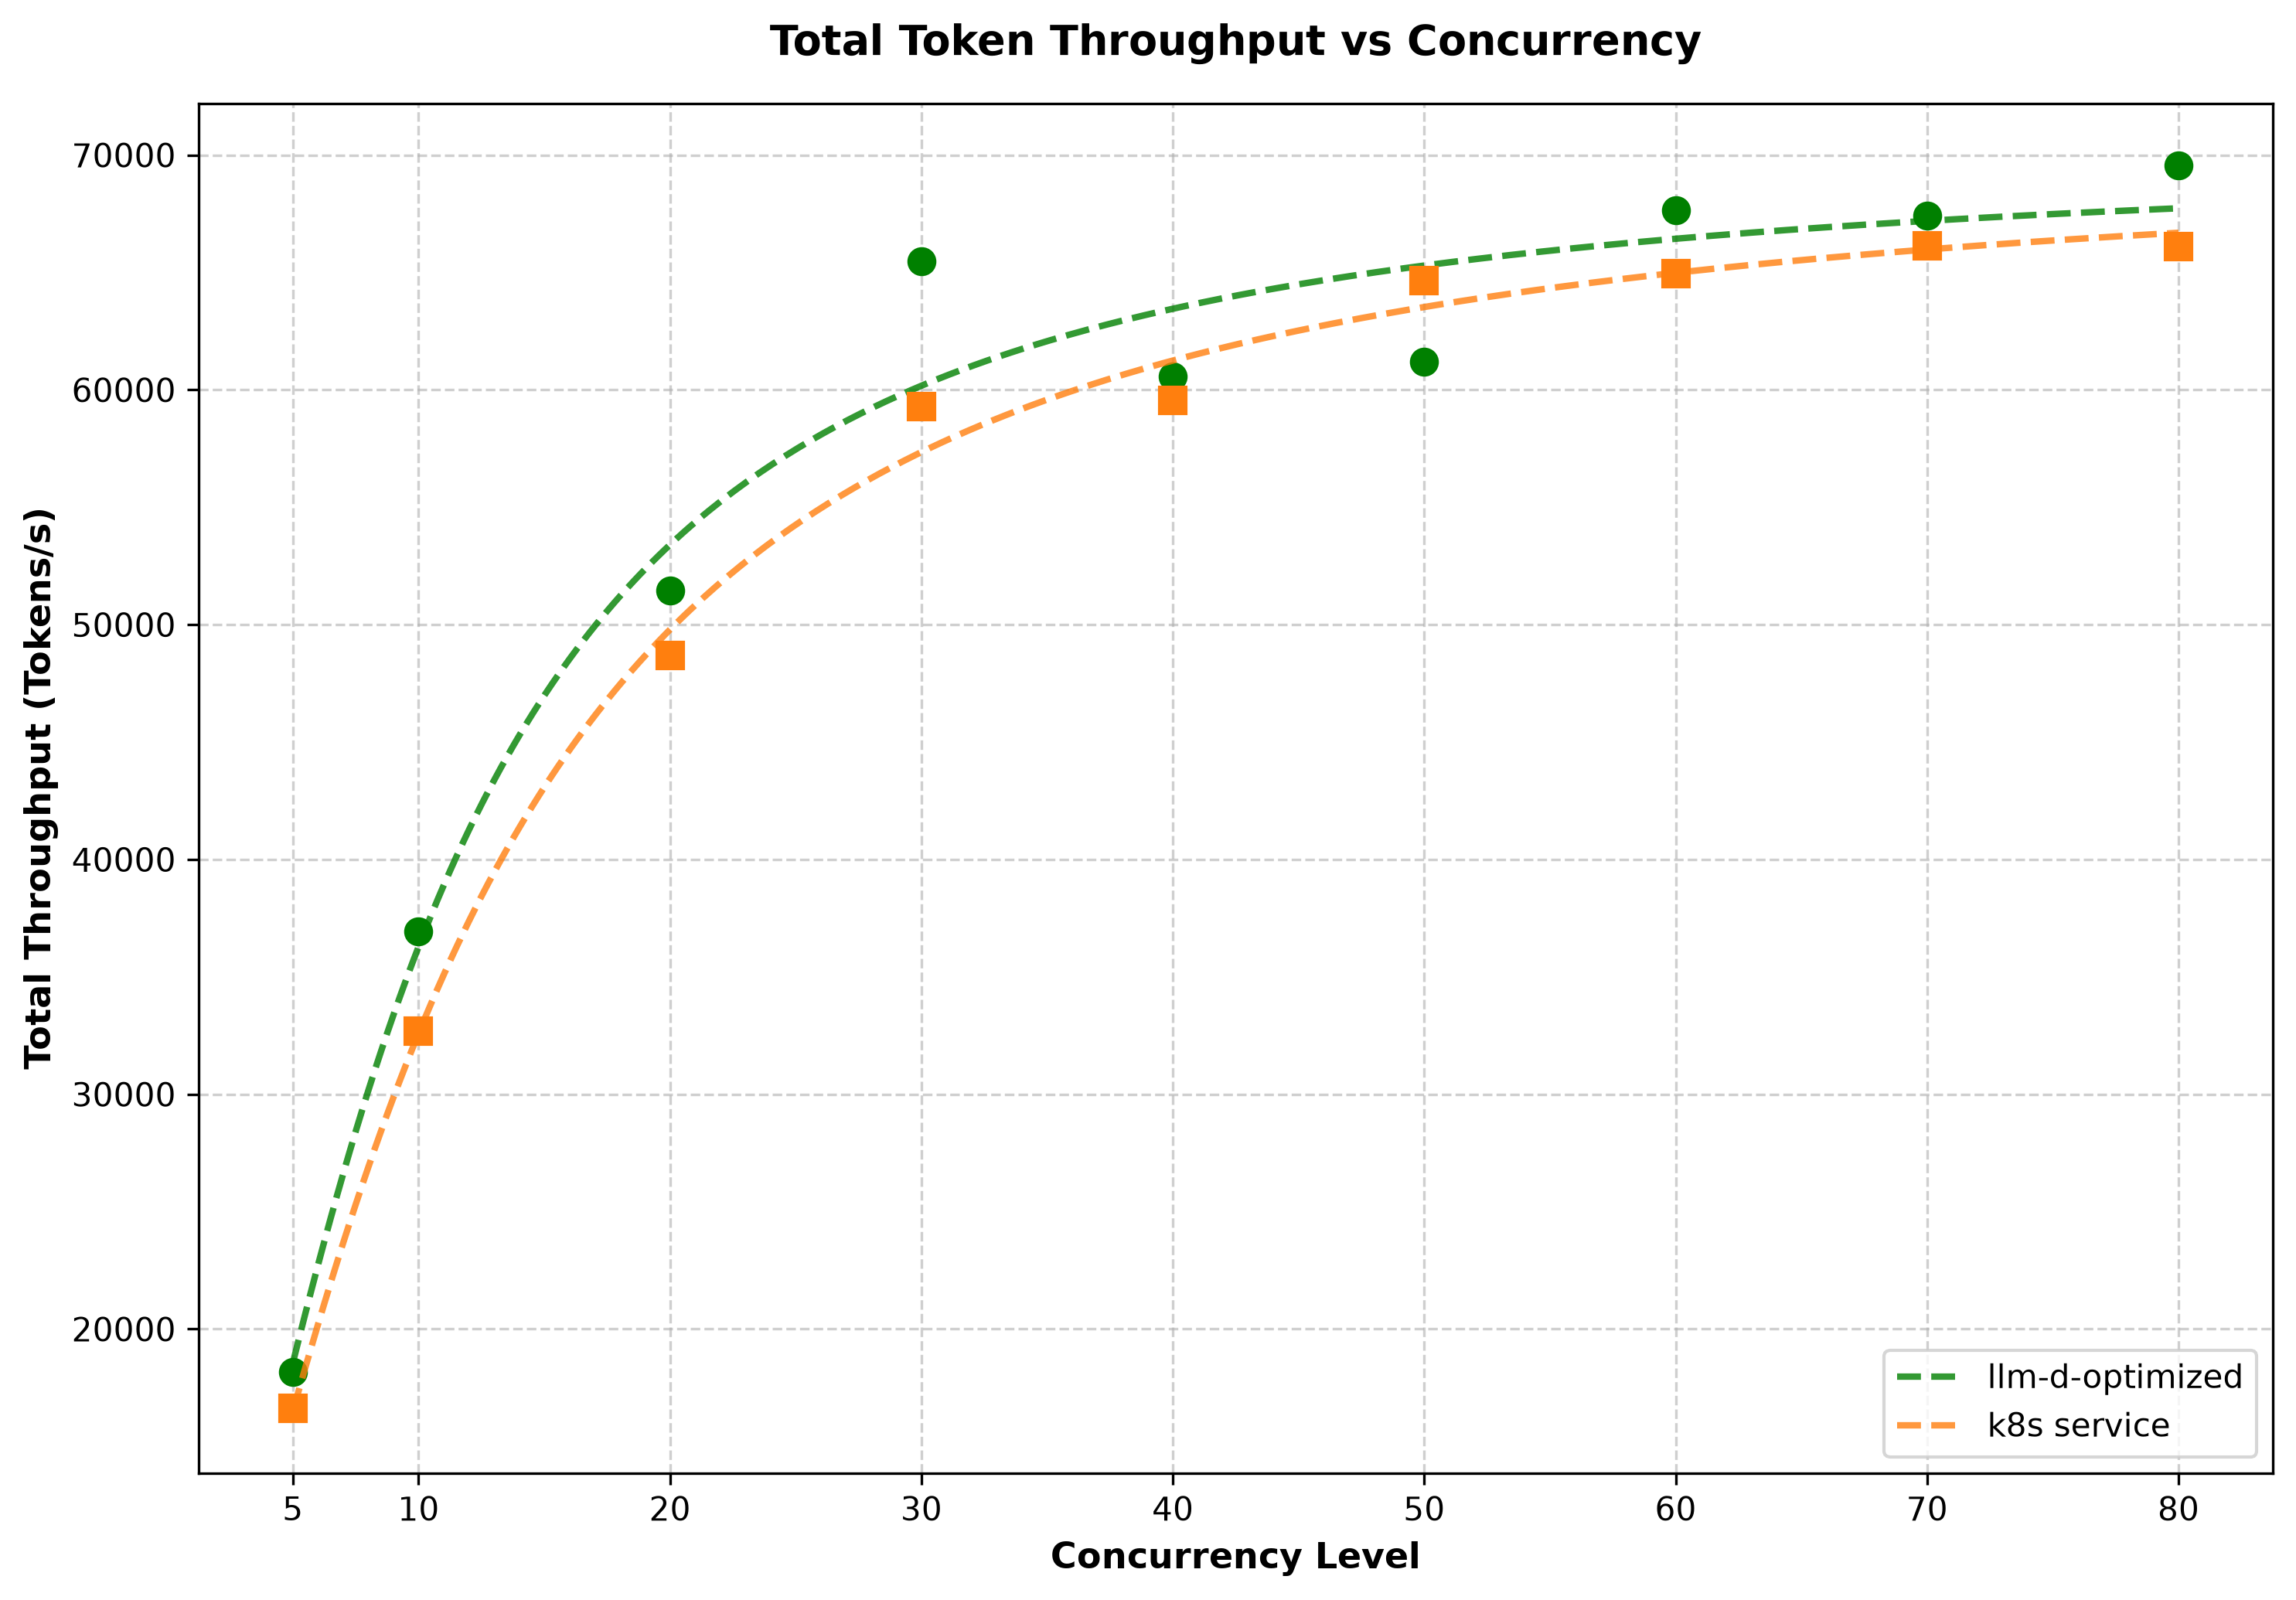
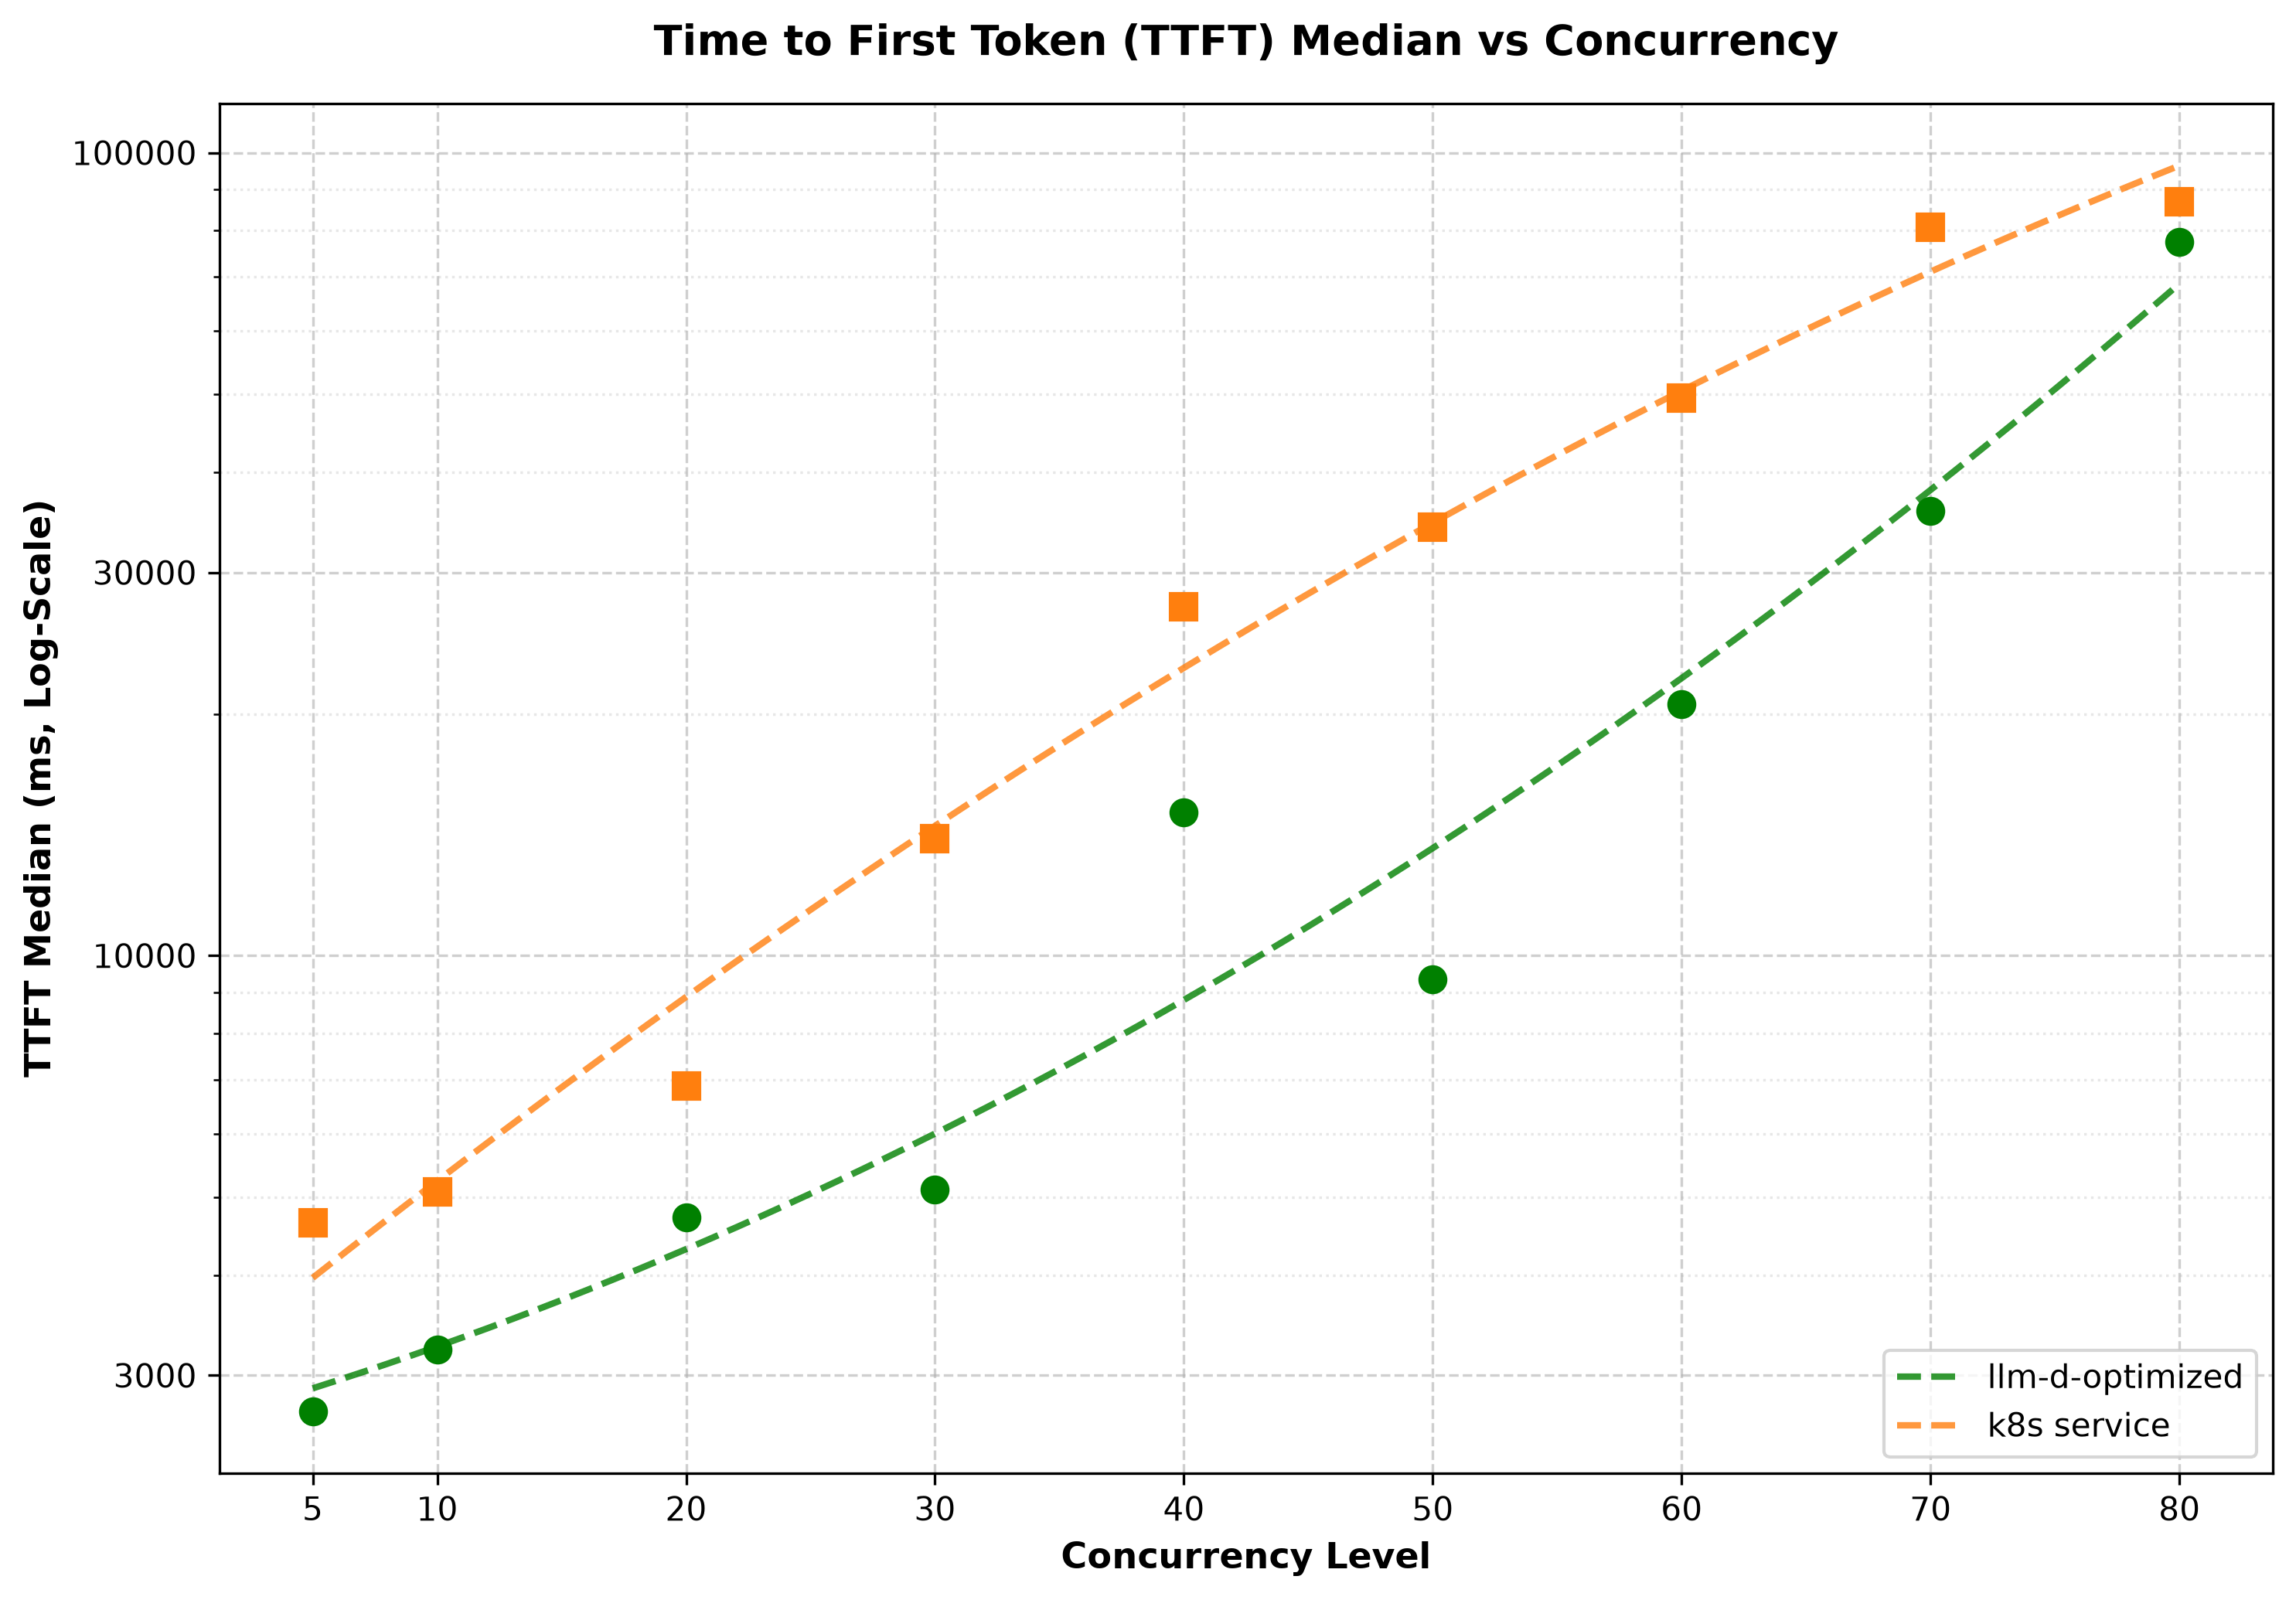
The results below are with 8 replicas of H200 GPU on the benchmark workload described above. Scaling concurrency up to 80 sessions.
Summary with 60 concurrent coding sessions
| Metric | k8s Service | llm-d-optimized | Δ Improvement |
|---|---|---|---|
| TTFT P50 (ms) | 49462 | 20543 | ⬇️ 58% |
| Total tokens / sec | 64958 | 67645 | ⬆️ 4% |
| Input tokens / sec | 64474 | 66716 | ⬆️ 3% |
| Output tokens / sec | 484 | 929 | ⬆️ 92% |
Latency Profiles
Cleanup
To remove the deployed components:
kubectl delete -n ${NAMESPACE} -k ${REPO_ROOT}/guides/models/${GUIDE_NAME}/modelserver/${ACCELERATOR_TYPE}/${MODEL_SERVER}/${INFRA_PROVIDER}/
helm uninstall ${GUIDE_NAME} -n ${NAMESPACE}

kubectl delete -n ${NAMESPACE} -k ${REPO_ROOT}/guides/recipes/modelserver/components/monitoring-pd --ignore-not-found=true
kubectl delete namespace ${NAMESPACE}