Topology as an End-to-End Contract: P/D Disaggregated Inference in llm-d on GKE



Lessons from bringing up RDMA-backed Prefill/Decode serving across H200, B200, GB200, and GB300 on GKE
Prefill/Decode (P/D) disaggregation splits LLM serving into two pools of workers: prefill workers process the prompt, and decode workers generate the output tokens. Between the two, every request hands its KV cache over the network. The path those bytes take (which NIC, which switches, how many hops) is set by three layers that don't coordinate by default: the platform decides which network paths exist at all, the resource allocator picks each worker's GPU and NIC, and the router picks which prefill worker pairs with which decode worker.
We learned how much that matters while bringing up llm-d's P/D path on four GCP GPU platforms: A3 Ultra (H200), A4 (B200), A4X (GB200 NVL72), and A4X Max (GB300 NVL72). The bring-up itself was a first: llm-d's P/D guide had no high-performance GKE RDMA recipe before this work built one on A3 Ultra, then carried the same allocation-and-transport contract through A4, A4X, and A4X Max (allocation). The problems we hit shared one shape: one layer lost what another knew, and the symptom appeared far from the cause.
The lesson is that topology is not only a transport optimization; it is an end-to-end contract spanning allocator, kernel, NIC, transport, engine, and router. Keeping RDMA fast depends on every layer holding its part: a mismatched GPU and NIC, a missing route, a silent fallback to TCP, or a topology-blind pairing anywhere along the way degrades the whole path. Concretely, the platform must discover topology, publishing each device's PCIe root, NIC, and rail as attributes Kubernetes can see. Allocation must preserve it, giving each worker a GPU and a NIC that belong together. The runtime must verify it, confirming that KV really moves over RDMA. And the router must consume it, pairing prefill and decode workers that are close on the network. Two results from our clusters show what that is worth:
- A silent fallback from RDMA to TCP is not a slowdown but an outage. Forcing one on purpose under benchmark load made 436 of 5,400 requests time out; eliminating one on A4X cut mean KV-transfer time by more than 93%.
- Mean time-to-first-token (TTFT) fell from 2.15 s to 1.157 s once each worker had a matched GPU and NIC and a verified RDMA channel, and then to 0.33 s, a further 3.5× reduction, once the router also paired workers by topology (evaluation).
An earlier post, Networking for Distributed Inference in llm-d, covered the transport stack itself: NIXL (the KV-transfer library), UCX (the communication library underneath it), and backend performance. This post follows topology from the platform through allocation and transport into routing.
The Problem: Every KV Handoff Is a Network Path
In aggregated serving, where one engine runs both prefill and decode, the KV cache never leaves the GPUs that built it. Disaggregation changes that. Prefill and decode run as separate pods that scale and fail independently, so each request's KV cache has to move from a prefill GPU to a decode GPU. On the machines in this post it moves by RDMA (Remote Direct Memory Access) over a dedicated RoCE (RDMA over Converged Ethernet) network.
One piece of network vocabulary matters throughout: the rail. Each GPU on these machines has its own RoCE NIC, and the NICs are wired into independent switching planes called rails (eight on A3 Ultra, four on A4 and A4X; A4X Max presents each of its four NICs as two logical NICs), with NICs in the same position on every node sharing a rail. A same-rail transfer stays on one plane; a cross-rail transfer climbs through the switching fabric to change planes. Figure 1 shows the three paths a KV transfer can take.
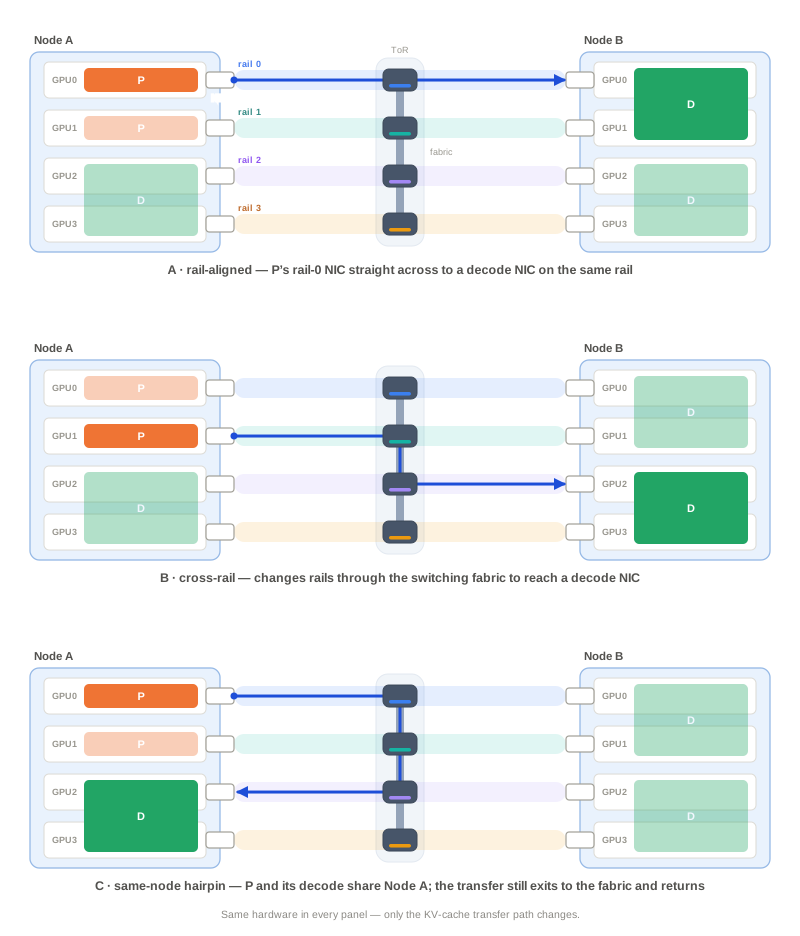
Figure 1: Three KV-transfer paths on the same hardware (illustrative layout, not a production node shape). Orange P marks prefill workers and green D marks decode workers; each GPU has its own NIC, and each NIC sits on a rail. Each panel shows one GPU-to-GPU transfer; in this post's benchmark, where one-GPU prefill workers feed four-GPU decode workers, each request makes several, one per decode GPU. How far up the switch tiers a path climbs also depends on placement, such as node distance and rack boundaries.
Why pods on the same node still use the network. Inside a single-process engine, GPUs share NVLink directly; separate pods don't by default. Crossing the pod boundary takes either host IPC with access to the peer pod's GPU, which weakens pod isolation, or, on the NVL72 platforms, a ComputeDomain, NVIDIA's DRA-managed way to share NVLink memory across pods through its IMEX (Internode Memory Exchange) service (NVIDIA's guide). We tried ComputeDomains on GB200 and transfers worked, but our recipes keep KV on RDMA, the path we have verified end to end on all four platforms, even when pods share a node.
The hairpin. Over RDMA, a same-node transfer takes the long way: GPU, PCIe, NIC, up to the rail's top-of-rack (ToR) switch (and further, if the destination NIC is on another rail), then back down to the other GPU's NIC. Whether that path works at all, and what it costs, depends on facts a topology-blind scheduler never sees: rail identity, PCIe roots, and whether the platform supports hairpin traffic.
Where this applies. Hairpins arise only when prefill and decode pods share a node, as in this post's partial-node deployment (one-GPU prefill and four-GPU decode workers on eight-GPU nodes). Everything else here applies to any deployment shape, because rail alignment, transport verification, and topology-aware routing govern every cross-node transfer too.
The Platforms
The four platforms are GCP machine shapes, described in Google's accelerator-optimized machine and GPU networking documentation. For this post they differ in four ways: NVLink domain size, how RoCE NICs map onto rails, how much GPU/NIC pairing Kubernetes can express, and whether same-node hairpin RDMA is available. DRA (Dynamic Resource Allocation) is the Kubernetes API for requesting devices by their attributes.
| Platform (GPU) | NVLink domain | RoCE NICs and rails | GPU/NIC allocation today | Same-node hairpin |
|---|---|---|---|---|
| A3 Ultra (8× H200, VM) | 8 GPUs, one node | 8× ConnectX-7 (CX-7) @ 400 Gbps, one per GPU; 8 rails | GPU and NIC in one DRA claim, same PCIe root | Supported |
| A4 (8× B200, VM) | 8 GPUs, one node | 8× CX-7 @ 400 Gbps, one per GPU; 4-way rail-aligned | Same as A3 Ultra | Supported |
| A4X (GB200 NVL72, VM) | 72 GPUs per rack, 4 per node | 4× CX-7 @ 400 Gbps, exposed as 4 VFs; 4-way rail-aligned | NICs through DRA; GPUs through the device plugin | Supported |
| A4X Max (GB300 NVL72, bare metal) | 72 GPUs per rack, 4 per node | 4× CX-8 @ 800 Gbps, exposed as 8 logical NICs (PFs), two per card | As on A4X, plus each CX-8's two PFs bound as a pair | Not available when tested |
NICs are exposed as virtual functions (VFs) on the VM-based platforms and as physical functions (PFs) on bare-metal A4X Max, where pods reach them through ipvlan interfaces. Placement matters too: rail-aligned traffic between GPUs in the same sub-block is one network hop, within a block at most two, and crossing blocks adds one more (networking overview). On A4X and A4X Max, a sub-block is one NVL72 domain of 18 nodes; NVLink carries tensor-parallel traffic inside it, while our recipes send KV between workers over the RoCE rails, inside a rack and across racks.
A link is not a route. In early bring-up, pods whose DRA claims didn't constrain rails often couldn't open RDMA connections: UCX connection timeouts, and RDMA_CM_EVENT_ADDR_ERROR during address resolution. The hardware was fine (on A3 Ultra, A4, and A4X, both cross-rail and same-node RDMA work), but a packet is only as routable as every layer beneath it. What was missing, in the pods' network setup, were the per-NIC routes and neighbor entries that UCX consults to decide whether a peer is reachable. Today the recipes handle this at the transport layer: our shared GKE base sets UCX_IB_ROCE_REACHABILITY_MODE=all, so UCX treats every RoCE address as reachable instead of consulting the host routing table, and workers no longer have to be restricted to same-rail pairs just to connect. That is a workaround, not a repair: it skips a check rather than restoring the missing state, and it helps only UCX. The durable fix belongs to the platform, injecting those routes and neighbor entries into the pods' network setup so that every RDMA consumer sees correct reachability. We traced the gap and raised it with the GKE networking team, which owns that platform-side injection.
One constraint up close: the hairpin. Bare-metal A4X Max did not offer same-node hairpin RDMA when tested, while the VM-based platforms do. Internal GKE analysis traced the difference below Kubernetes: on the tested bare-metal path, local RDMA address resolution produced frames with identical source and destination MAC addresses, which the physical ToR dropped. Constraints like this depend on how a platform is layered and can change between releases. Our part is the same on every platform: treat them as topology data rather than assumed defaults, and align the deployment within them so the physical link delivers what it was built for. Where hairpin is unavailable, anti-affinity keeps prefill and decode on separate nodes; where it is available, they can share a node, as in the evaluation deployment.
Why alignment is worth it. Rail alignment pays off in three ways. Bandwidth: within a sub-block, a rail-local transfer crosses a single rail switch and never touches the uplinks above it, so concurrent flows cannot collide in the fabric's multipath load balancing (ECMP), a risk even non-blocking fabrics carry. Latency: we measured about 2–3 µs per additional switch layer, small next to a request but large next to a single RDMA operation. On A4X, a 48 MB transfer took 6.6 ms, about 15% of one 400 Gbps link's capacity over that time, so transfer time is set more by per-operation overhead than by bandwidth, and each request's handoff spans more than a thousand memory descriptors. NIXL overlaps them, but limits on in-flight operations and completion boundaries keep path latency from being fully hidden, and transfer time lands directly in TTFT. Predictability: within a sub-block, a rail-local path has no multipath choice to make, so its latency is reproducible from run to run.
Alignment continues inside the transport layer, where NIXL and UCX manage NIC allocation. By default, UCX attempts to maximize performance by spreading each GPU's transfers across up to two of its highest-bandwidth NICs. While this strategy generally works well, specific hardware architectures require more deliberate alignment to prevent severe bottlenecks. On A3 Ultra and A4 platforms, each pair of GPUs shares two ConnectX-7 NICs through a single PCIe Gen5 switch. Because the default configuration routes traffic through both NICs, simultaneous large-message transfers from both GPUs collide and contend for the same switch resources, degrading overall bandwidth. Forcing a strict 1:1 mapping between GPUs and NICs, by setting UCX_SINGLE_NET_DEVICE=y alongside NIXL's default UCX_MAX_RMA_RAILS=2, eliminates this interference and boosts large-message bandwidth on A3U/A4 by 62% (Figure 2). This optimization depends on fixes in the next UCX and NIXL releases (1.22.1 and 1.4.1, including openucx/ucx#11650); on current releases, leave UCX_SINGLE_NET_DEVICE unset to prevent performance regressions. The A4X platform presents a different routing trap: because all NICs report equal bandwidth, current UCX releases bottleneck the system by funneling all traffic through the first listed interfaces, an issue resolved by another patch in the same upcoming UCX release (openucx/ucx#11547) that properly distributes the load. Finally, across all VM-based platforms (A3 Ultra, A4, and A4X), guest-to-host address translation adds PCIe transactions that make strict ordering highly inefficient. Enabling PCIe relaxed ordering (UCX_IB_PCI_RELAXED_ORDERING=y and IBV_ACCESS_RELAXED_ORDERING=1) bypasses this overhead and significantly improves throughput.
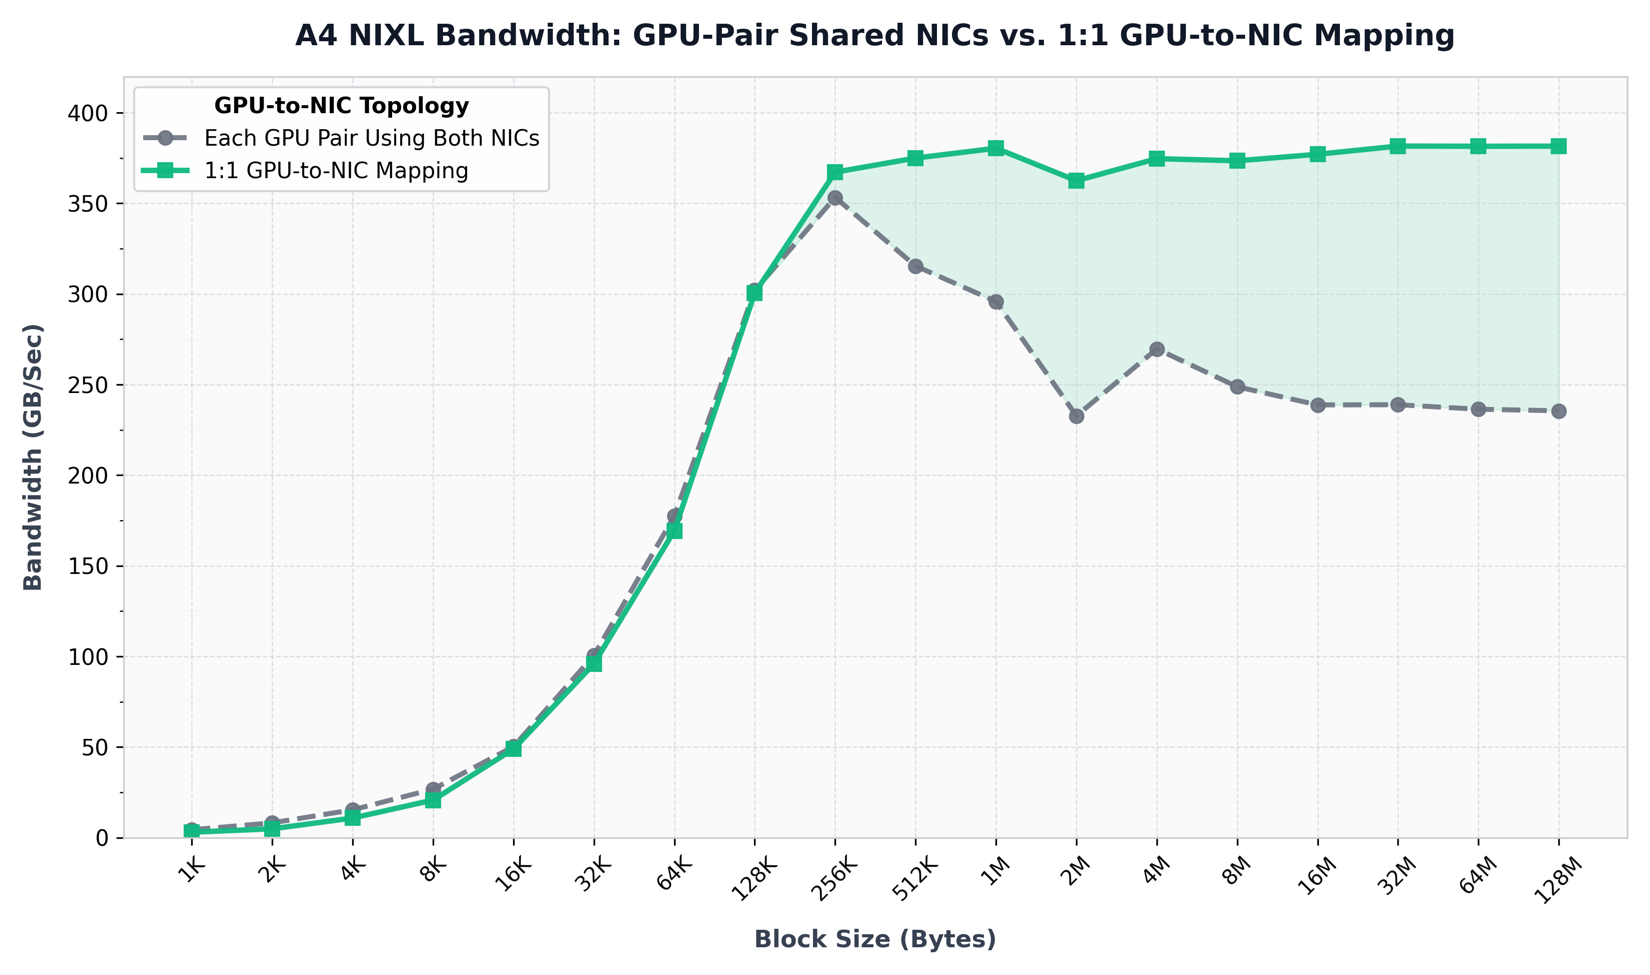
Figure 2: NIXL bandwidth on A4 by transfer block size, with each GPU pair using both NICs (the default) versus a 1:1 GPU-to-NIC mapping. Beyond 256 KB, the shared configuration drops to about 235 GB/s at the largest sizes, while the 1:1 mapping holds near 380 GB/s: the 62% gap cited above. Measured by the GKE networking team with the upcoming UCX and NIXL fixes.
None of this is unique to GKE: every fabric has paths that exist, paths that need routing behind them, and paths a security policy forbids, and no real cluster gives every GPU pair the same reachability and cost. A deployment has to be built within its fabric's constraints, not against them, which is why topology awareness pays off.
Allocation: Keep Each GPU Next to Its NIC
The allocation rule is the same on every platform: each worker's GPU and NIC should sit under the same PCIe root. With GPUDirect RDMA the NIC reads KV straight from GPU memory, and a shared PCIe root keeps those bytes from crossing root complexes or CPU sockets. Platforms differ in how much of the rule they can express. Two Kubernetes features do the work: DRA claims, which request devices and can require them to share an attribute such as a PCIe root, and CEL (Common Expression Language) selectors, which filter devices inside a claim.
A3 Ultra and A4. Both the GPU and the NIC come from DRA, so a single ResourceClaimTemplate asks for the pair and constrains it with matchAttribute: "resource.kubernetes.io/pcieRoot": both devices land under the same physical PCIe root. We introduced this pattern in llm-d#1821, the guide's first GKE P/D recipe. It was later refactored into the shared gke/base that all GKE overlays build on (llm-d#2062), and llm-d's SGLang P/D guide adopted the same shape (llm-d#2059). The evaluation's channel-verified and topology-scored rungs ran on A3 Ultra, where this claim enforces alignment.
A4X. In the tested recipe, only the NIC side lives in DRA. Each worker's claim requests a dedicated NIC through the mrdma.google.com DeviceClass (llm-d#2043), while GPUs come from resources.limits through the device plugin. The two are allocated independently, so nothing ties a worker's GPU to the NIC under its PCIe root: a one-GPU prefill worker can get a GPU and a NIC under different roots. On these Grace-based platforms such a pair still works over GPUDirect RDMA, with a smaller penalty than on x86 hosts. A same-root constraint needs both devices in one claim, so it applies only when GPUs are also allocated through DRA, in which case the A3 Ultra claim carries over unchanged. GKE's managed DRANet, the DRA driver behind these NIC claims, already places them by network connectivity; a GPU claim adds the tie to a specific GPU's PCIe root.
A4X Max. Same split as A4X, plus a platform rule. Each CX-8 exposes two logical NICs (PFs), which appear in the pod as two interfaces on the same card (for example gpu0ipvlan0 and gpu0ipvlan1), and the pair must be bound together for the RDMA link to come up. Our dedicated overlay (llm-d#2068) uses DRA's firstAvailable to list four alternatives, one per card (nic-group-0 through nic-group-3), each a CEL prefix match that takes both PFs of that card, so whichever card the scheduler picks, both PFs come from it. As on A4X, this binds the NIC side only; GPU-to-NIC PCIe-root matching also needs GPUs under DRA and a PCIe-root attribute on the ipvlan interfaces themselves (dranet#261).

Figure 3: One allocation rule, four platforms. The gray bar is the rule itself: GPU and NIC under the same PCIe root. Solid anchors are enforced by the recipe; dashed anchors apply only when GPUs are also DRA-allocated (on A4X Max, also when its ipvlan interfaces carry their parent NIC's PCIe root). The green bar inside the CX-8 box is the PF pair binding, a connectivity requirement rather than PCIe-root alignment. A3 Ultra and A4 share the first column.
Topology preservation has to be a contract the platform upholds, not a patch reapplied per platform; the takeaways return to what that takes upstream.
Verify the Transport You Actually Have
UCX, the communication library underneath NIXL, chooses a transport when it first connects to each peer, from whatever is usable at that moment. If the RDMA devices cannot be opened or cannot reach the peer, whether from a misconfiguration or a link that is down, it selects the next usable transport, TCP included, without an error. On general-purpose infrastructure that is the right default, because reachability comes first. On a fabric built for GPUDirect RDMA it works against you: nothing fails at the serving layer, and only UCX's own logs record the choice.
That silence is what makes a fallback expensive under P/D load. Transfers get slow but don't break, so connections hold, health checks pass, and requests keep arriving, while memory held by in-flight transfers piles up until the decode side runs out: latency first, then out-of-memory errors, two subsystems away from the cause. We hit this on two platforms. On A3 Ultra, early bring-up fell back to the datacenter network before the RDMA routing environment was complete. On A4X, KV transfers fell back to TCP and consistently took more than 100 ms, with peaks of several seconds, while nothing at the serving layer reported a failure. The cause, found only by inspecting the running process, was the serving process loading the RDMA userspace (verbs) library bundled in its container image instead of the host's. Binding it to the host's verbs stack, through LD_PRELOAD and host-driver mounts added in llm-d#2043, restored the RDMA path. Later gIB releases (GKE's host networking stack) stopped injecting their own verbs libraries into pods, so the process now sees a single verbs stack and current overlays drop the workaround (llm-d#2058); on any image, it is still worth checking which verbs library the serving process actually loads (check 3 below).
Make failure loud. Fixing one cause doesn't prevent the next, so we also pin UCX's transports with an explicit UCX_TLS allowlist, rc_mlx5,rc,cuda_copy,cuda_ipc,sm,shm,self, contributed in the same PR. It removes TCP and limits wire transports to the reliable-connection (RC) family, plus CUDA and shared-memory transports for local copies; the rc alias also admits UD (unreliable datagram) for connection setup only. The allowlist doesn't make a working RDMA path faster. It changes what happens when RDMA breaks: the first connection to each peer fails with an explicit "unreachable" error instead of quietly serving over TCP. It selects the transport type (UCX logs showed rc_mlx5), not the NIC or rail, which still come from allocation, and it ships in the A4X and A4X Max overlays; our A3 Ultra benchmark deployments set the same value. Because NIXL connects lazily, on the first request a prefill/decode pair serves, that error would otherwise surface under traffic; llm-d's preflight checks narrow the gap by testing the pod's network path before vLLM starts.
Result. With the host library binding and the allowlist in place on A4X, UCX logs confirmed KV traffic on RDMA for the whole run. Transfers averaging about 48 MB completed in about 6.6 ms (P90 about 8 ms), down from more than 100 ms during the fallback: a reduction of more than 93%. These are per-transfer times reported by the engine, not wire-level measurements. The multi-second peaks disappeared, because the path that caused them no longer exists.
Checks for development. When you need a closer look, the transport's own logs and counters are more reliable than a dashboard, and each check takes minutes on a live pod:
# 1. Which transport was selected: run workers with
#      UCX_LOG_LEVEL=info UCX_PROTO_INFO=y
#    UCX then prints the transport it chose for each connection
#    (you want rc_mlx5).

# 2. Where the bytes go: during a transfer, RDMA port counters climb
#    while eth0 carries only light pod control-plane traffic.
#    KV-scale volume on eth0 means a fallback path is live.
#    (port_xmit_data counts 4-byte words.)
watch -n1 'cat /sys/class/infiniband/*/ports/*/counters/port_xmit_data; \
           cat /sys/class/net/eth0/statistics/tx_bytes'

# 3. Which verbs library the serving process actually loaded:
grep libibverbs /proc/<pid>/maps
Together, the checks read the chain both upstream and downstream of a transfer.
Metrics for production. Bring-up checks catch problems once; production needs standing telemetry, because drivers, kernels, and fabric neighbors keep changing. Three properties made RDMA NIC telemetry useful for us:
- Per-NIC granularity, keyed to the NIC's PCI address or interface name (
mlx5_Nnumbering can differ between nodes), to confirm traffic rides the intended rail and spot imbalance. - Congestion and error counters alongside throughput: Congestion Notification Packets (CNPs), out-of-sequence packets, ACK timeouts, and discards are often the clearest sign of contention on shared rails.
- Resolution of seconds, not minutes, at least on a node-local endpoint, because minute-level averages flatten P/D's millisecond-scale transfer bursts.
Topology Must Reach the Router
Allocation and verification make the candidate paths usable; the router decides which one each request takes: pairing a prefill worker with a decode worker fixes the route of that request's KV. llm-d v0.9 ships the router side of this contract. A topology-extractor plugin reads each endpoint's host, rack, zone, and region from configurable pod labels (llm-d-router#1678). A topology-affinity filter and scorer (llm-d-router#2299) then compare each candidate with the endpoint the router picked in the first stage: the filter keeps candidates within a minimum affinity of it (host by default), and the scorer ranks them by proximity, host first. The order we recommend is prefill first: with stageOrder: prefill-first on the disagg-profile-handler (llm-d-router#2342), the router picks the prefill worker on KV-cache reuse, then picks the decode worker by topology, with the filter and scorer in the decode profile. The filter fails open when topology data is missing or no candidate qualifies, so locality never makes a request unroutable. The labels themselves come from outside the router, the separation our prototype design argued for: the router never talks to cloud-provider hardware APIs, and a DRA plugin, webhook, or operator discovers the physical layout and labels each pod, because rail fabrics, NVLink domains, and TPU ICI slices each encode topology differently. On GKE, nodes carry cloud.google.com/gce-topology-block, -subblock, and -host labels (Topology Aware Scheduling); propagated to pods, they can fill those levels, for example sub-block as rack.
Two rules define the policy we recommend:
- Feasibility is a hard constraint, enforced below the router. Paths the platform does not offer, such as same-node hairpin on a platform without it, are ruled out by allocation, placement, or network policy, never left to a fail-open router filter.
- Cost is a soft score. Among feasible paths, prefer the pairing with the lowest expected transfer cost. Locality is the leading signal but not the only one. When the preferred domain is saturated, spill over to a more distant worker rather than queue behind a "perfect" path.
What we measured. Before the upstream plugins landed, we measured what topology-aware pairing is worth with a prototype: a hand-populated hierarchical locality label on each pod, ordered from widest to narrowest scope (for example datacenterA.leaf4.rail1.host2), and a longest-prefix-match scorer patched into the router. The prototype ran in the opposite order, decode first: the router picked the decode worker, then scored each prefill candidate against it. Either order scores proximity between the same pair; prefill first also lets KV-cache reuse choose the prefill worker. For the benchmark, the topology score had a dominant, effectively hard weight: while capacity remained, each decode worker was paired with rail-matched prefill workers on the other node, and at this load those pools had headroom throughout.
The router controls less than it might seem. Picking a one-GPU prefill worker fixes the sending NIC and rail, but each request's KV then fans out to all four decode GPUs, each pulling its own shard; the engine's tensor-parallel layout and UCX's device choice decide those legs, not the router (see Alignment continues inside the transport layer). Some legs of every request cross rails whatever the pairing, so the evaluation's gain came from pod-level pairing alone, with no per-GPU control.
Hard in the benchmark, soft in production. Dominant weighting was the right tool to isolate the effect, and it worked. In production, locality belongs in a soft score: pools saturate, workloads share clusters, and a hard constraint turns every capacity dip into queueing. As a soft score, topology composes with the router's load- and cache-aware signals, which is the shape the v0.9 scorer takes; its companion filter adds a minimum-affinity floor that fails open. The v0.9 levels run from host to region; our prototype's labels went down to the rail. The prototype is not shipping. When locality should dominate or yield within the shipped scheduling profiles is still an open question.

Figure 4: Topology-blind versus topology-scored pairing, in the recommended prefill-first order: the router picks the prefill worker on KV-cache reuse, then scores decode candidates by proximity to it. The policy shown (prefer locality, spill over when saturated) is what the scorer in #2299 enables alongside load-aware scorers. Our measured runs used the prototype scorer, decode first with dominant weighting, pairing across nodes on matching rails (results in Figure 5). Arrows show pairing choice, not wire paths.
Evaluation
We ran two experiments on a two-node H200 cluster: TCP versus verified RDMA, and a three-rung TTFT ladder that adds one part of the contract at a time. We then repeated the top rung 25 times on other hosts and regions.
Setup. The benchmark served gpt-oss-120b on 16× H200 GPUs across two GKE A3 Ultra (a3-ultragpu-8g) nodes, with eight one-GPU prefill replicas and two four-GPU decode replicas (tensor parallelism TP=1 and TP=4). In the ladder deployment, each node hosted four prefill workers and one decode worker. Load came from inference-perf through the llm-d-benchmark harness, running the guide's benchmark unmodified: 45 QPS for 120 seconds (5,400 requests with fixed 5,000-token inputs and 250-token outputs), followed by a drain with a 300-second client timeout. Every configuration used the same vllm/vllm-openai:v0.23.0 serving image. Each ladder rung is one 120-second run, and the top two rungs ran on the same deployment. The public guide reproduces everything except the prototype scorer.
What a silent fallback costs. We ran the same workload with KV forced onto UCX's TCP path over the datacenter network (DCN), where a silent fallback lands. That RDMA outperforms TCP is expected; the point is what a fallback means in production. It is not a graceful degradation but an unacceptable failure: of 5,400 requests, 436 timed out, and completed requests averaged 223 s of latency, finishing long after the 120-second load window. The system was queuing, not serving. (This is UCX's TCP path at this load, not TCP in general.) With verified RDMA, all 5,400 requests completed, and port counters showed an instantaneous peak of 359 Gbps on one link, about 90% of the ConnectX-7's 400 Gbps line rate. The same verified transport configuration underlies the ladder's upper two rungs.
The TTFT ladder.
- Unconstrained control: 2.15 s mean TTFT, P90 3.92 s.
- Channel-verified (deterministic DRA allocation and verified RDMA on the router's default scheduling, no topology-aware routing): 1.157 s mean, P90 1.587 s.
- Topology-scored pairing: 0.33 s mean, P90 0.41 s.
Reading the ladder. The first step, 2.15 s to 1.157 s, comes from allocation and transport together: both rungs ran the router's default scheduling, with no topology-aware routing. With unconstrained allocation, GPU/NIC pairings and paths changed from one deployment to the next: all worked, but many were longer and less predictable than the rail-aligned paths the fabric is built around. The public numbers tell the same story once their order is clear. The guide's earlier P/D reference was measured on another platform; our DRA-based GKE recipes landed next, without a published score; the current GKE baseline, in the same range as this rung, was measured after them, alongside router scheduling updates. In our GKE deployments the P/D path did not run over RDMA without DRA-based allocation, so there is no without-DRA point to compare against, and our default-scheduling runs had already reached this level. The step belongs to allocation and transport. The second step, 1.157 s to 0.33 s, comes from topology-scored pairing on the same deployment, workload, and verified channel: another 3.5× in mean TTFT, with P90 falling from 1.587 s to 0.41 s. Topology-scored pairing puts the transfers the router controls on shorter, less contended paths, and at a load where transfers overlap, those per-transfer savings (see Why alignment is worth it) accumulate instead of hiding. With everything else held fixed, we attribute the 3.5× to topology-scored pairing at the system level. Throughput was the same in the control and topology-scored runs (43.8 and 43.9 requests/s against the offered 45 QPS), so the gain did not come from serving less load.
Repetition. We re-ran the topology-scored configuration 25 times with the same deployment configuration (same manifests, same scripts, same topology shape), spread across hosts and regions so the result would not hinge on one host or regional fabric. It held steady: mean TTFT averaged 0.33 s across runs (range 0.22–0.39 s, standard deviation 0.04 s), and per-run P90 averaged 0.45 s (standard deviation 0.05 s). The ladder's run is typical: its mean also rounds to 0.33 s.

Figure 5: Left: the DCN/TCP configuration could not sustain the offered load; verified RDMA could. Right: the TTFT ladder, from unconstrained control to channel-verified to topology-scored. All TTFT values are means; percentiles are in the text.
Limitations. The testbed is two nodes, so the topology decision space is small: these numbers demonstrate the mechanism, not its ceiling. Whether disaggregation itself beats aggregated serving for a given workload is out of scope; this post takes P/D as given and optimizes the network path underneath it.
Takeaways and Open Questions
The layer where a failure appears is rarely the layer where it starts. A silent transport fallback surfaced as latency and then as decode-side memory errors; missing per-NIC routes surfaced as connection timeouts; topology-blind pairing surfaced as tail TTFT. Each component looked fine on its own; the composed path was what went wrong. SemiAnalysis's ClusterMAX 3.0 review of managed GPU clusters reports the same pattern from the provider side: outside the NVL72 rack, "providers pick the topology, the cabling, and how Kubernetes or Slurm hands the fabric to a job. We found problems at every layer." That is why the lessons form a contract between layers rather than a checklist inside any one of them:
- Discover. The platform publishes physical topology (PCIe root, NUMA node, rail and NIC identity) as device attributes, not just device counts.
- Preserve. Allocation carries those attributes through. The test for any allocation API: can the scheduler co-constrain two devices on a shared physical attribute?
- Verify. Runtime evidence, not configuration intent, is the source of truth for the transport path.
- Consume. The router acts on topology. Path feasibility (enforced below the router) and capacity are hard constraints; among feasible paths, locality is a soft preference.
Topology is one axis among several; the same decision also weighs capacity, KV-cache reuse, node pressure, and network load. The contract keeps topology in one consistent form, so a placement policy can weigh it against the others instead of rediscovering it.
Upstream Kubernetes is standardizing the attributes discovery needs. KEP-4381 defines resource.kubernetes.io/pcieRoot, the cross-driver attribute our A3 Ultra claims match on, and it already travels beyond GKE: llm-d's Intel XPU RDMA recipe uses the same constraint, and Amazon EKS's EFA DRA driver documents it for aligning EFA interfaces with NVIDIA GPUs. Two gaps remain. On the NIC side, kubernetes-sigs/dranet#261 asks for virtual interfaces, such as A4X Max's ipvlan interfaces, to inherit their parent NIC's PCIe root; on the GPU side, GPUs must be DRA-allocated for a claim to match on it. When both hold, the A4X NIC-only claim and the A4X Max CEL chain can collapse into the one generic claim A3 Ultra and A4 use today.
The contract also reaches past P/D. With ModelExpress P2P, a pod loads model weights by pulling them from a peer pod's GPU memory over RDMA; our A3 Ultra overlay for it (llm-d#2423) reuses the same claims and UCX settings and moves 33.51 GB per TP rank in 0.70 s, roughly 380 Gbps.
Open question: larger fabrics. The router plugins already select prefill and decode workers by topology, from host to region. What multi-leaf clusters add is calibration and congestion: how strongly topology should weigh against KV-cache reuse and load when nearby workers saturate, how to account for live uplink load and RoCE congestion that static labels do not capture, and whether sub-node workers need labels down to the rail, as our prototype used.
The deepest lesson of the four-platform bring-up is that per-platform assumptions rot as hardware evolves, so topology should be discovered and consumed as data rather than baked into deployment logic. A stack that treats topology as data absorbs the next platform by learning new attributes; one that bakes it in starts over. From H200 to GB300, the per-platform details changed every time; the contract carried over. The recipes behind the allocation and transport results, including DRA templates, transport configuration, and overlays for A3 Ultra/A4, A4X, and A4X Max, live in the llm-d P/D disaggregation guide and ship with llm-d v0.9. Try them with the v0.9 topology-affinity plugins enabled, measure what topology is worth on your own clusters, and join the discussion in the llm-d community.