Run 40% more post-training experiments on the same GPUs with llm-d time-slicing


When we introduced co-operative time-slicing in llm-d, we made a claim: if RL phases become schedulable units, independent jobs can share accelerators with near-zero waste. Today we're backing that claim with a measured, end-to-end proof. For research teams, the claim cashes out as one thing: more experiments per week on the GPUs you already have.
OpenRL, an open source, Kubernetes-native, Tinker-compatible, self-hosted fine-tuning service built on the llm-d time-slicing stack, runs many post-training jobs, SFT and reinforcement learning alike, concurrently on the same GPUs.
Key results at a glance
By time-slicing three distinct workloads (two RL, one SFT) on different base models, we achieved:
- 40% more experiments in the same timeframe: On the same two GPUs, the three workloads finished in 39 minutes time-sliced versus 54 minutes run one after another, at just three jobs.
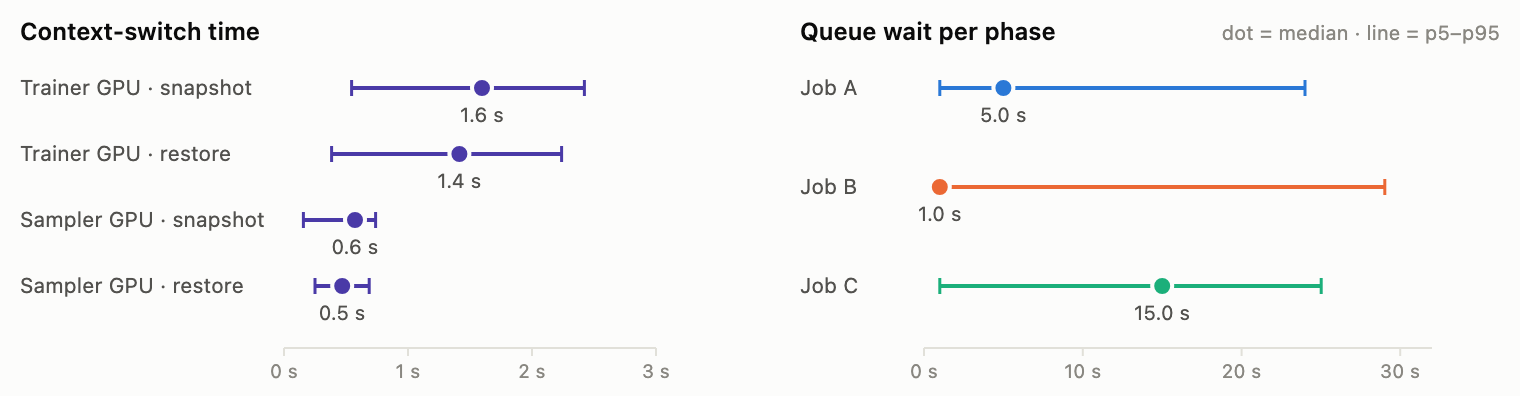
- Every experiment started instantly: No job waited for a predecessor to finish; phase-level queue waits ran 1–15 seconds (median).
- 67% reduction in hardware footprint: Cut the required physical GPU count from 6 dedicated GPUs down to just 2 shared GPUs.
- 38% savings in GPU-hours vs. concurrent dedicated runs: Reduced total compute consumption from 2.10 to 1.30 GPU-hours against six dedicated GPUs running all jobs concurrently, and from 1.80 to 1.30 GPU-hours (28%) against the same two GPUs running the jobs serially.
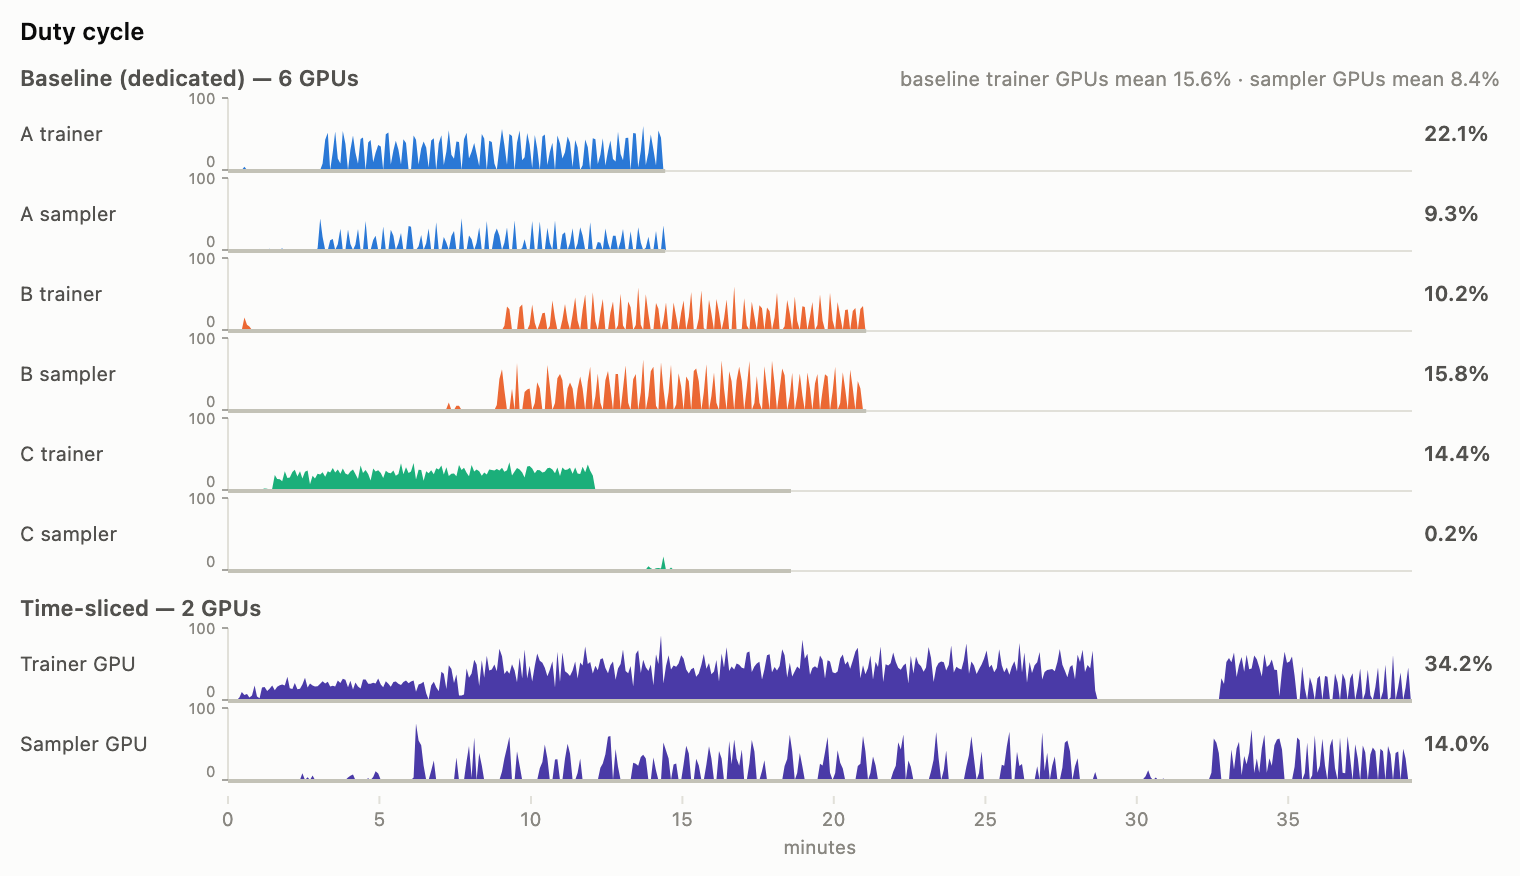
- Over 2x increase in GPU duty cycle: Boosted average trainer GPU utilization from 15.6% to 34.2%, with ample headroom for more jobs before saturation.
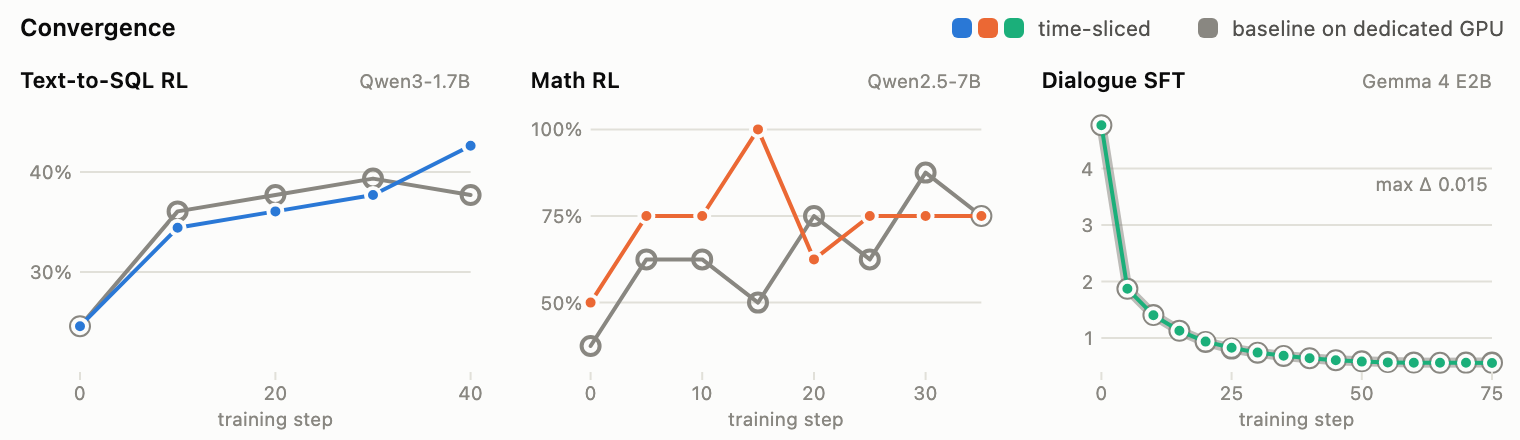
- Zero quality degradation: All three workloads achieved identical convergence curves compared to their dedicated-GPU baselines.
This post walks through what the time-slicing platform provides, what a managed RL service (RLaaS) adds, and what the combination measures.
The real bottleneck: researcher iteration speed
One researcher is fine-tuning a customer support assistant on internal tickets, another is training a text-to-SQL agent on proprietary database schemas, and every idea in the backlog is waiting on the same scarce GPUs. How many experiments actually run each week comes down to how those GPUs are shared.
For parameter-efficient methods like LoRA, engines like vLLM and PyTorch already let many jobs share one frozen base model. Full-parameter fine-tuning is the extreme case: every training step can mutate all weights, so each job needs the whole model, the whole optimizer state, and the whole GPU.
This has forced organizations into expensive choices:
- Queuing: forcing research teams to wait in line, slowing development velocity and time to market.
- Siloed, dedicated GPUs: giving every team its own capacity, which caps how many experiments can run in parallel, yet still sits idle 30-74% of the time as RL alternates between generation and training.
llm-d time-slicing eliminates this trade-off: jobs start the moment they are submitted, and even full-parameter customization runs at a fraction of the hardware cost.
Case study: OpenRL
Here is how that works in practice. The llm-d time-slicing stack supplies the machinery — the Snapshot Agent that snapshots and restores a worker's state between VRAM and host memory, the TimeSlice Orchestrator that grants jobs exclusive access in turn, and a client library that wraps two RPCs, acquire() and yield(). What a managed service must add is exactly one thing: knowing where its jobs' phase boundaries are. That turns out to be the easy part.
The API is the phase structure. OpenRL exposes Tinker-style primitives — generate_samples for rollouts, forward_backward for training, and optim_step for the weight update. Every job arrives pre-decomposed into the schedulable units time-slicing was built around. The service wraps acquire() and yield() around each work unit, users write an ordinary training loop and get time-sliced accelerator sharing without knowing it exists.
The integration comes down to two moves:
- Oversubscribe the hardware. The OpenRL orchestrator provisions dedicated trainer and sampler workers per job and binds multiple jobs' workers to the same physical GPUs using Kubernetes Dynamic Resource Allocation. With per-job worker processes, jobs can bring different stacks — PyTorch FSDP or Megatron, vLLM or SGLang — to the same shared hardware.
- Wrap GPU work units in acquire/yield. Each worker loop pops a work unit from its job queue, calls
acquire(), runs the work, and callsyield(). The orchestrator and Snapshot Agent handle the rest — granting exclusive access in turn and context-switching job states. Work that doesn't need the GPU, like persisting checkpoints, runs from the host copy and never takes the lock.
What we measured
Small demonstration runs like these (three jobs, two GPUs) are time-slicing's hardest case. The numbers below show the mechanism and its overheads, not a general platform benchmark or a TCO estimate: at production scale, phases run for minutes, switch costs amortize toward zero, and the reclaimable idle only grows.
To validate the architecture, we ran a highly heterogeneous, concurrent workload representing typical enterprise workloads:
- Job A (Text-to-SQL RL): Fine-tuning Qwen3-1.7B on the Spider dataset.
- Job B (Math RL): Fine-tuning Qwen2.5-7B on GSM8K.
- Job C (Dialogue SFT): Supervised fine-tuning of Gemma 4 E2B on MultiWOZ.
All three jobs were multiplexed onto a shared pool of two NVIDIA H100 GPUs (one for training, one for sampling).
All three jobs converged — matching baseline learning curves. The text-to-SQL job climbed from 25% to 43% in response accuracy, the math RL job roughly doubled its eval accuracy, and the dialogue SFT job's eval loss fell from 4.77 to 0.56 over 80 steps — a curve point-for-point identical to its baseline run. Overall, time-slicing changed where the jobs ran — not what they learned.
Higher resource efficiency. With one dedicated GPU per worker, these three jobs would hold six GPUs — a trainer and sampler each. Given the inherent dependency between trainer and sampler in synchronous RL, those GPUs sit largely idle — gaps the job itself cannot fill. Time-slicing fills them with other jobs' work: the same jobs run on two GPUs, lifting duty cycles roughly 2x compared with their dedicated-GPU runs.
Minimal system overhead. Context switches cost 0.5–1.6 seconds (median). Queue waits per phase run 1–15 seconds (median) — highest for the SFT job, whose short steps queue behind the RL jobs' longer phases.
The full comparison:
| GPUs provisioned | Workload run time | GPU-hours | |
|---|---|---|---|
| Dedicated, all concurrent | 6 | 21 min | 2.10 |
| Shared, jobs run serially | 2 | 54 min | 1.80 |
| Time-sliced | 2 | 39 min | 1.30 |
- Versus six dedicated GPUs — time-slicing provisions two-thirds fewer GPUs and pays for ~38% less GPU time.
- Versus two GPUs running jobs serially — identical hardware, but time-slicing finishes the workload ~28% sooner, as it reclaims idle windows.
The trade: an individual experiment runs 1.9–2.5x longer than it would on six dedicated GPUs. But that comparison assumes the six GPUs exist. With two, the real alternative is the queue, where an experiment is not slower, it is not running at all until its predecessor finishes. Time-slicing puts all three in flight at once on the same two GPUs, and the batch collectively finishes sooner than queuing them one after another. The reclaimed idle time turns the wait into experiment throughput.
What's next
We're rolling out a selective state offload backend on Snapshot Agent that allows snapshotting specific GPU memory regions — LoRA adapter weights, accumulated gradients, optimizer state — while the shared base model stays resident. One interface now does it all: whole-process parking for full-parameter jobs, region-level parking for LoRA jobs. In early testing, offloading LoRA adapters through this backend delivered a 2.8x gain in concurrent LoRA jobs on a single NVIDIA L4 trainer GPU.
Get started today
If you are building or scaling a multi-tenant post-training platform, you can start getting efficiency gains today:
- Deploy the time-slicing stack today
- Run OpenRL and get this integration out of the box.
Acknowledgements
Thanks to Edwin Hernandez, Jessica Chen, Ling Lin and Shuby Mishra for bringing this to life.